1
 →
Local-first code intelligence graph for MCP and CLI. Builds a persistent map of your codebase so AI coding tools read only what matters
tirth8205/code-review-graph is an open-source project on GitHub, mainly written in Python. Local-first code intelligence graph for MCP and CLI. Builds a persistent map of your codebase so AI coding tools read only what matters It currently holds 32,469 stars and 2,959 forks with 192 open issues, and was last pushed on 2026-10-29 (repository created 2026-02-26).
Git Homed tracks it on the AI Agent Skills Trending board and on the AI AI Agent Skills Trending list.
A local code knowledge graph that gives AI coding tools precise review context over MCP.
English | 简体中文 | 日本語 | 한국어 | हिन्दी


Usage · Commands · FAQ · Troubleshooting · What's new · Changelog · GitHub Action · Reproducing the benchmarks · Roadmap · All docs
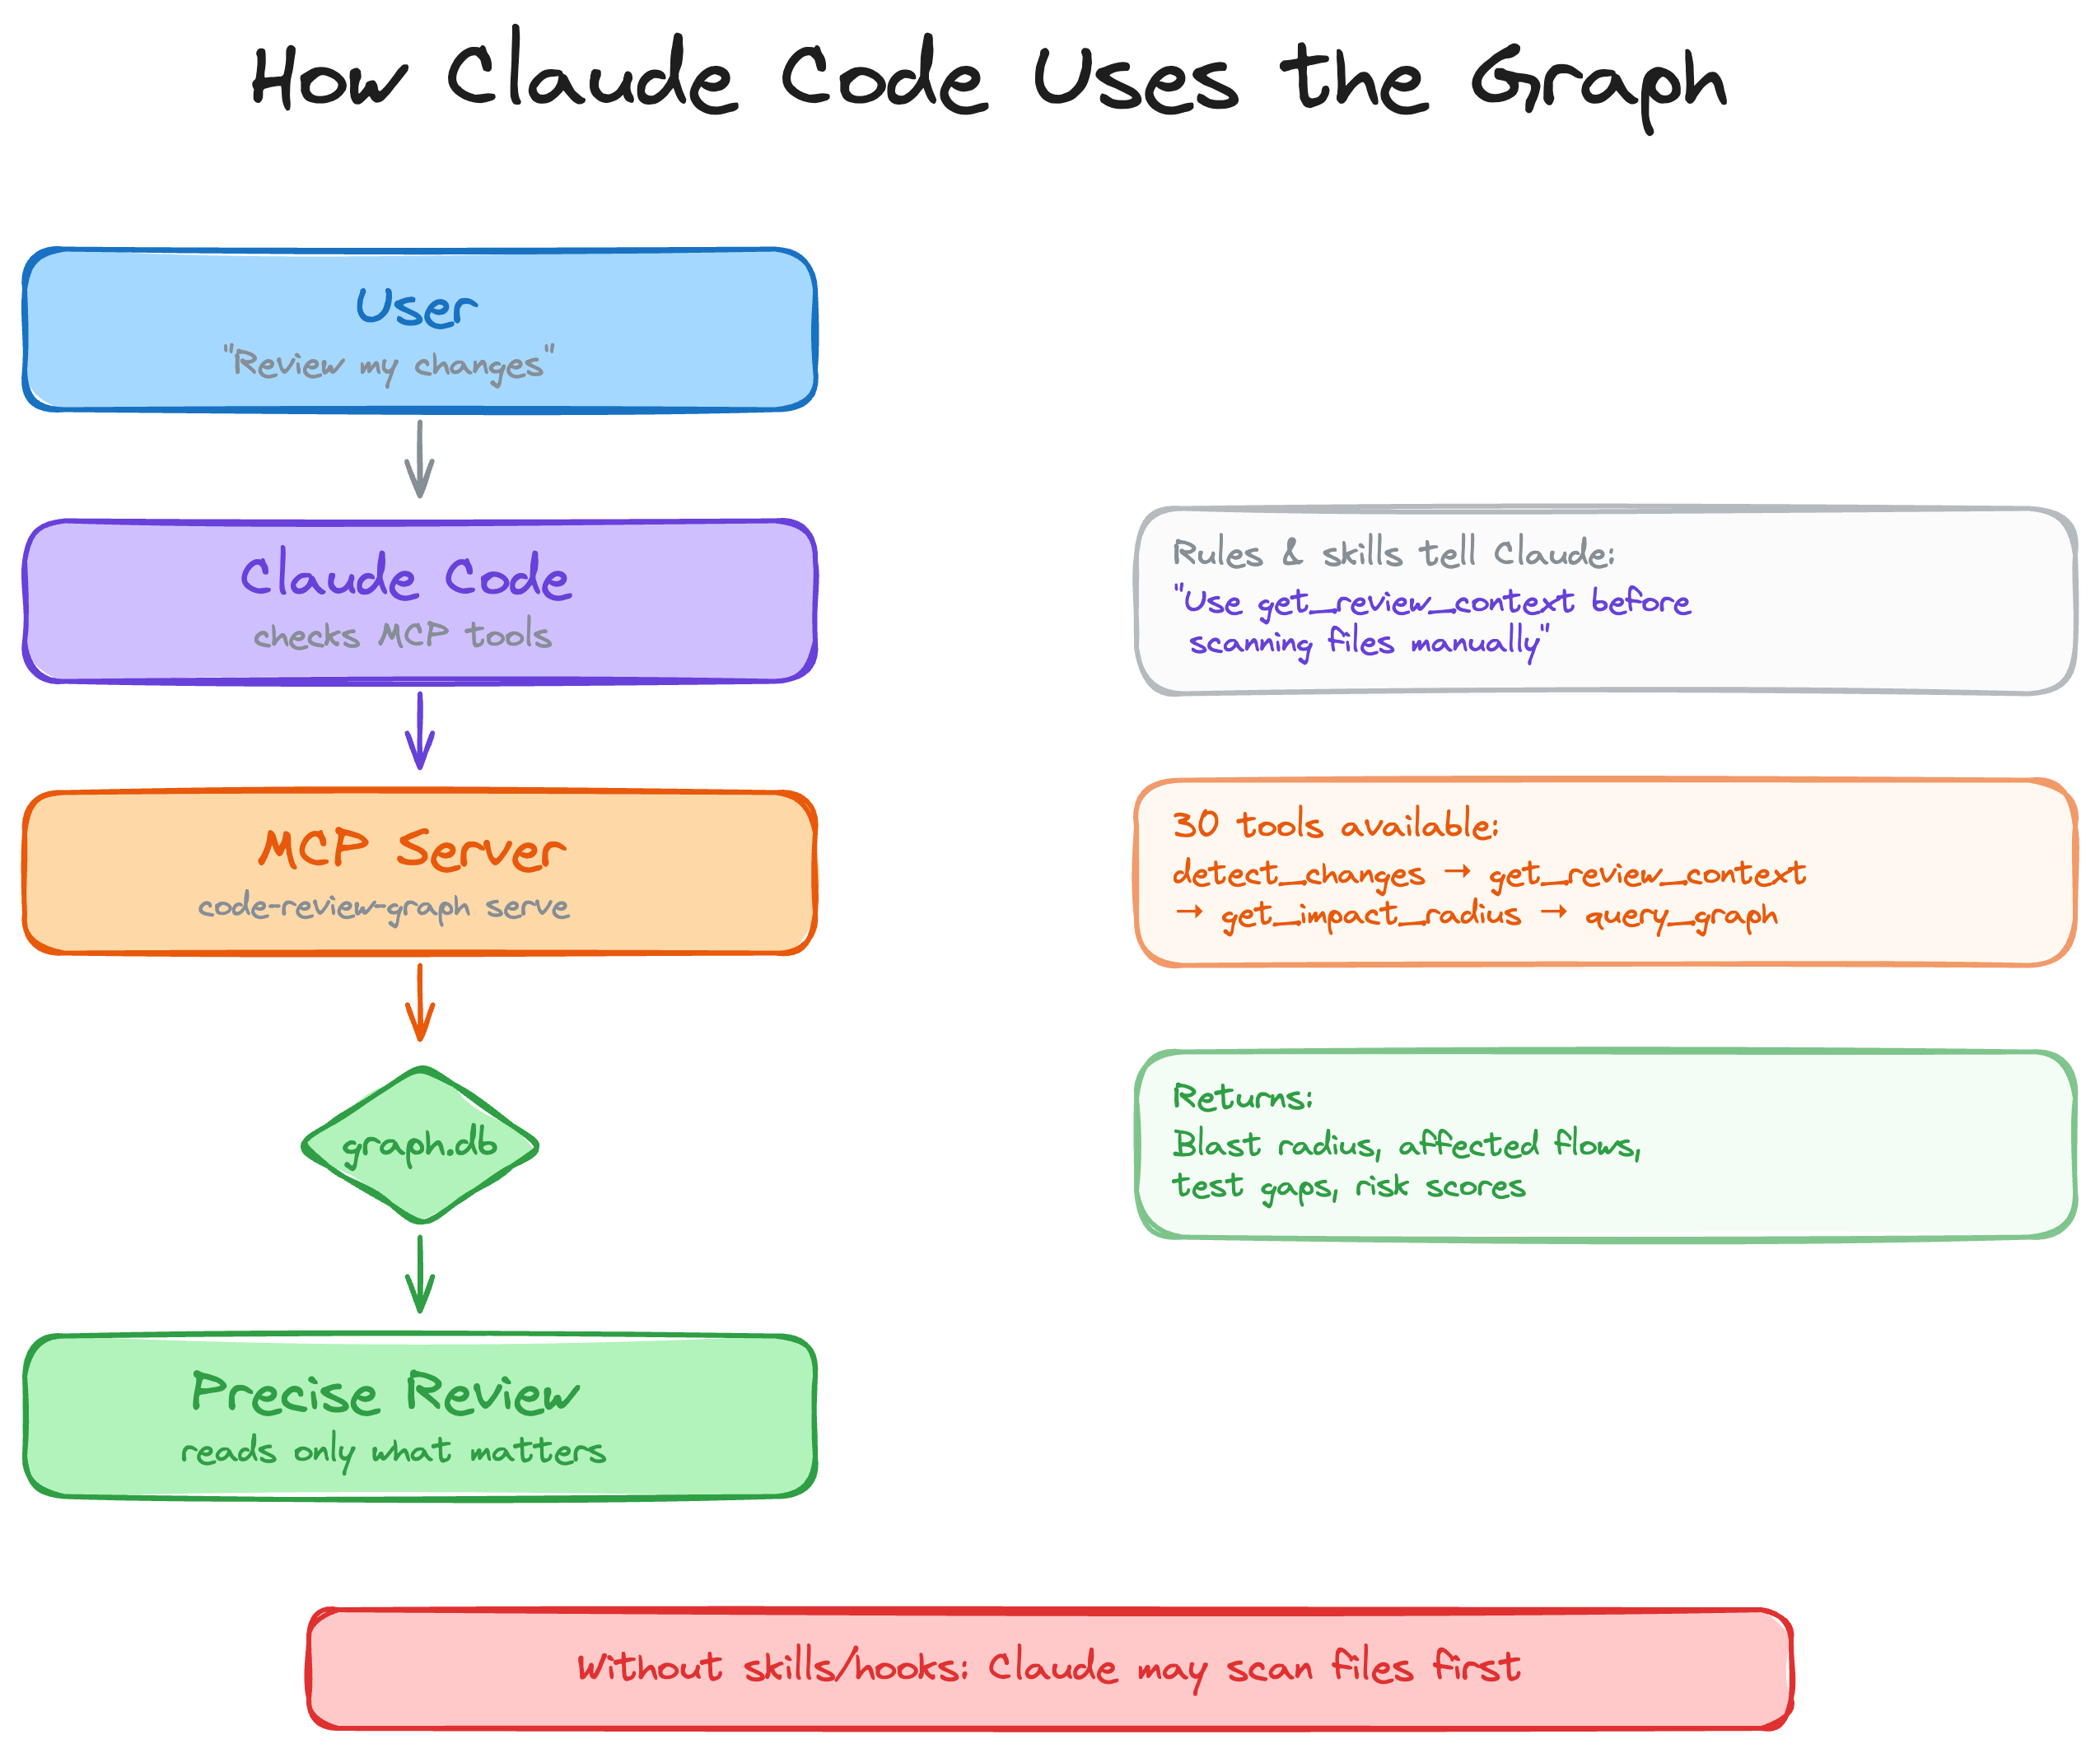
AI coding tools often re-read large parts of a codebase to review a change. code-review-graph builds a structural map of the code with Tree-sitter, keeps it updated incrementally, and serves compact context over MCP, so the assistant reads only the files a change touches.
What it does
install sets up each tool it finds.Requires Python 3.10+.
uv tool install code-review-graph      # or: pipx install / pip install code-review-graph
code-review-graph install              # set up the AI coding tools found on this machine
code-review-graph build                # parse the codebase
code-review-graph detect-changes --brief  # see what your last change touches
Restart the editor or tool, then open the project and ask the assistant:
Review my changes
Undo everything with code-review-graph uninstall (preview with --dry-run). If something does not work, run code-review-graph doctor: it checks the setup and changes nothing.
install changes, and how to preview it firstinstall looks for AI coding tools on this machine and sets up only the ones it finds. For each it writes an MCP server entry, installs hooks and skills where the tool supports them, and adds graph instructions to its rules file. It then names the tools it did not find; add one anyway with install --platform NAME.
Nothing is written until install has listed the files it will change and you have answered its question about instruction files. With no terminal, as when an AI agent runs it, it takes the default answer, yes, and says so; --no-instructions skips those files. install --dry-run shows each change as a diff and writes nothing. Restart the editor or tool afterwards.
The MCP entry and every hook run the copy of code-review-graph that ran install. The MCP entry uses poetry run or uv run inside a Poetry or uv project, uvx when install itself ran from uvx or uv tool install, and otherwise the Python that ran install. Hooks name that Python (or uvx), and run the code-review-graph on PATH if it is gone. After an upgrade, run install again.
The files install writes, such as .claude/ and .mcp.json, stay visible to git in case your team commits them. Until git tracks them, build and reviews leave them out, so your first review shows your own change; install lists them in .code-review-graph/install-manifest.json. install --gitignore adds the ones that run created to a marked block in .gitignore; uninstall removes the block.
For Codex, the installer also places a global code-review-graph Skill under
$CODEX_HOME/skills/code-review-graph/ (default:
~/.codex/skills/code-review-graph/). It prefers CRG MCP tools and falls back
to the bundled read-only CLI when MCP is unavailable; a missing, empty, or
stale graph never triggers an implicit build or update. WSL and Windows Codex
runtimes have separate CODEX_HOME directories and tool inventories, so
install and refresh the runtime that will execute the task.
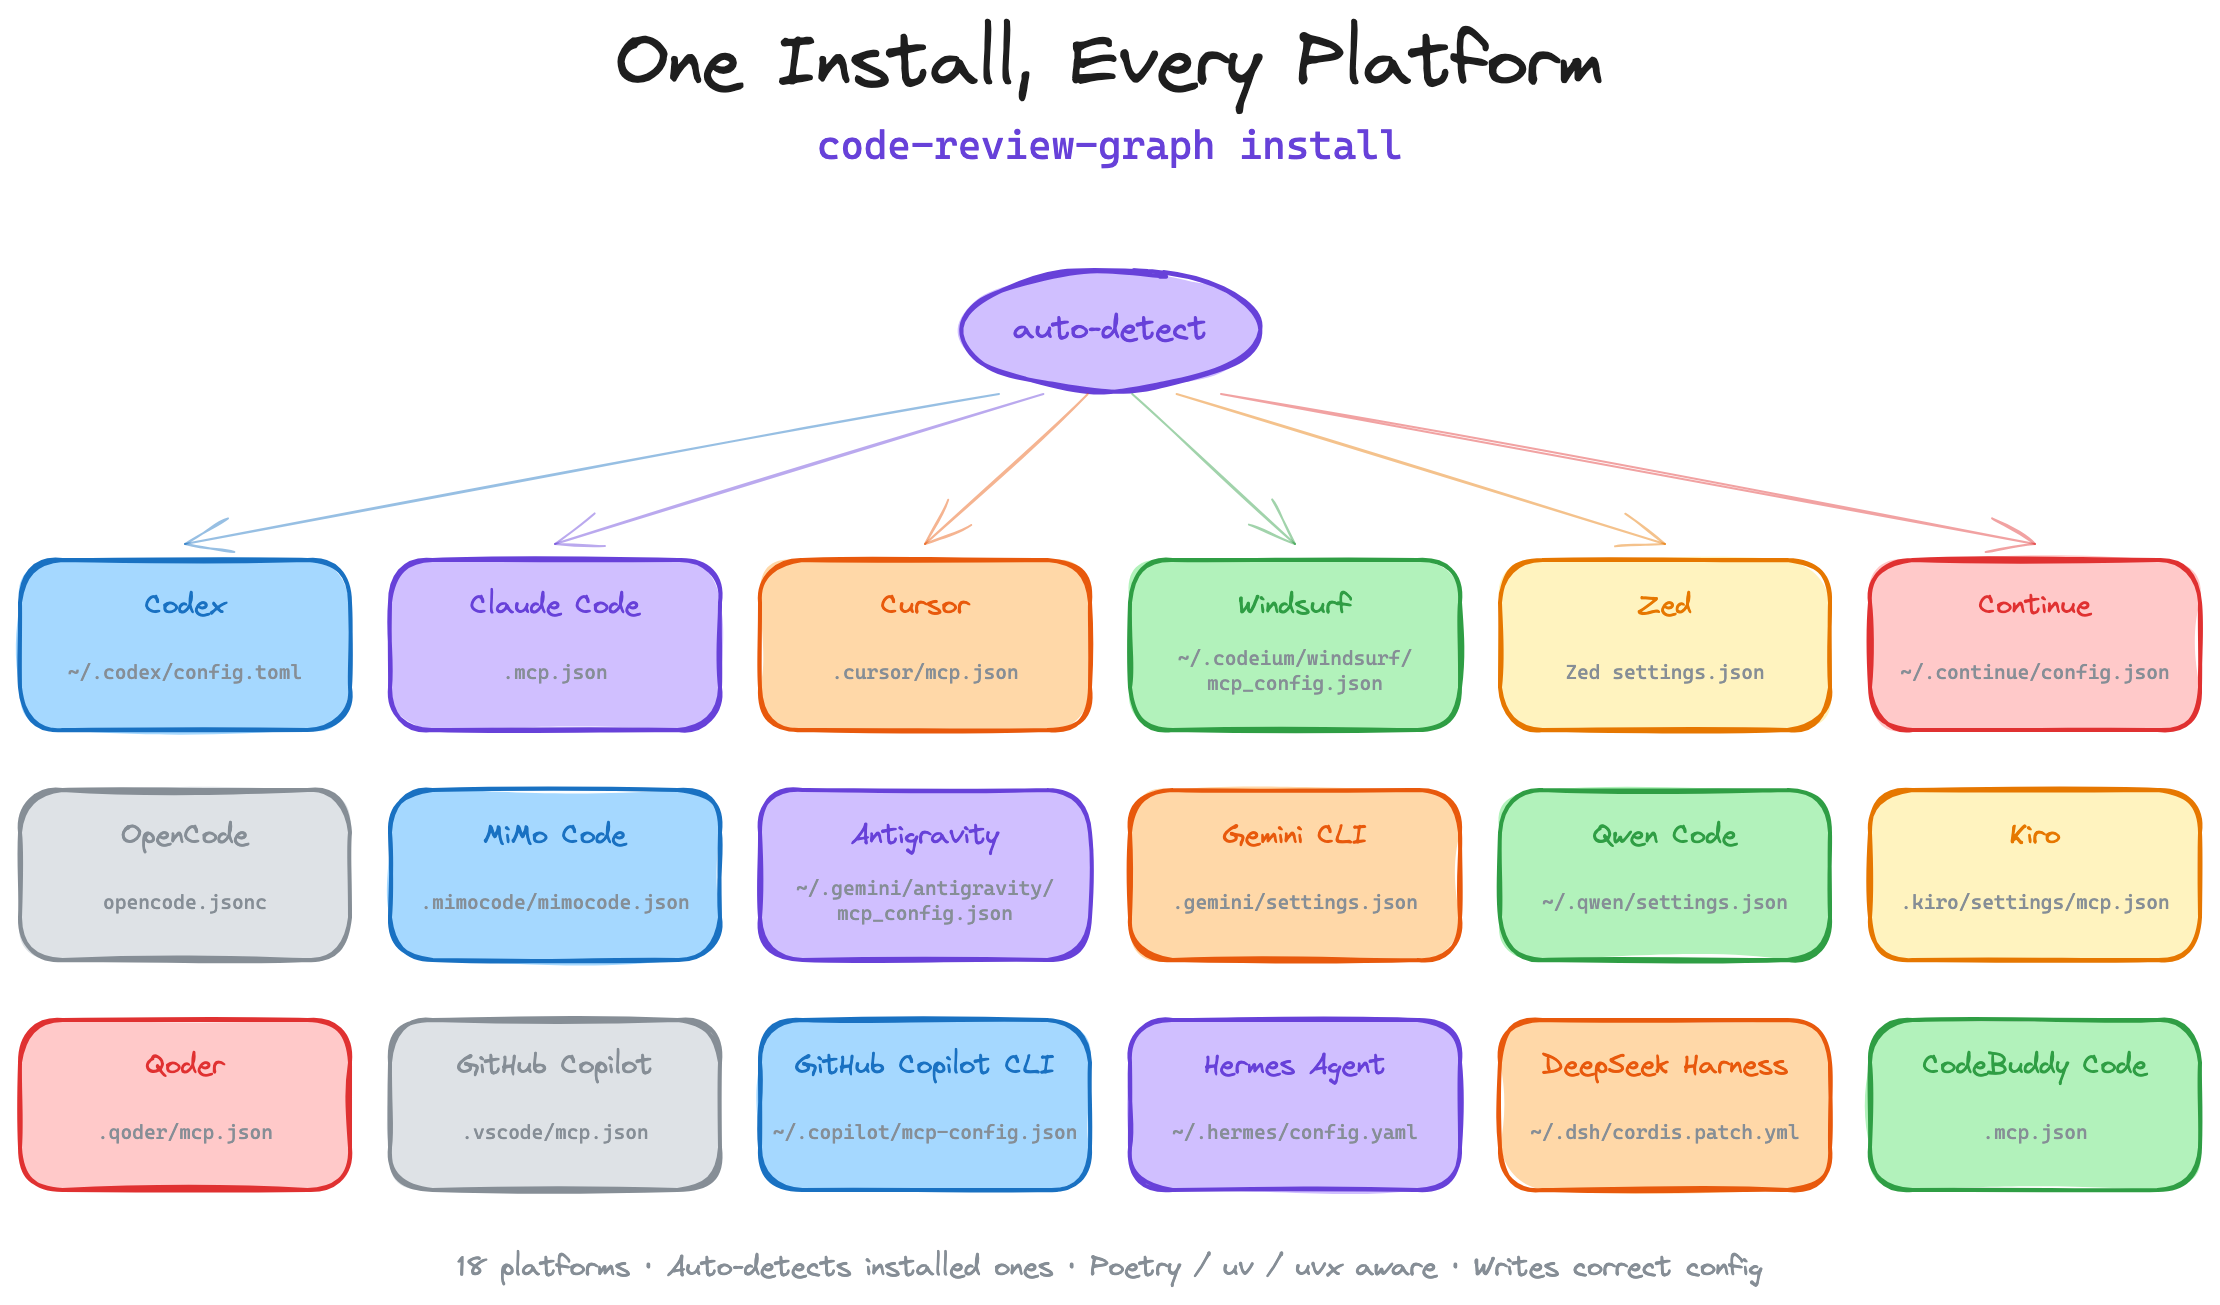
To configure one platform, pass --platform with one of codex, claude-code, cursor, windsurf, zed, continue, opencode, mimo, antigravity, gemini-cli, qwen, kiro, qoder, copilot, copilot-cli, codebuddy, hermes, or dsh:
code-review-graph install --platform cursor
code-review-graph install --platform codebuddy
A platform named this way is set up even when install does not find it. Config file locations are listed in docs/USAGE.md.
uninstalluninstall removes CRG-owned files and entries from a Git or SVN working tree and leaves other MCP servers, hooks, skills and JSONC comments alone. Run it from anywhere inside the tree. Shared config files are replaced atomically, so a failed write leaves the original intact. A config file install made, which git does not track and which holds nothing else, is removed along with the empty folders install made. With no terminal it takes the default answer, no, and says to pass --yes.
code-review-graph uninstall --dry-run    # preview only
code-review-graph uninstall              # preview, confirm, apply
code-review-graph uninstall --yes        # apply without prompting
code-review-graph uninstall --all-repos  # also clean every registered repository
code-review-graph uninstall --keep-data  # remove integrations, keep graph databases
code-review-graph uninstall --keep-user-configs --repo .  # this project only
Build time scales with repository size; a cold build of a ~3,000-file repository took about 40 seconds (measured). After that, hooks and watch mode keep the graph updated. If some files fail to parse, the result has status partial and names them in its summary; the CLI also prints a Warning: line on stderr, and those files keep their previous graph rows. A build that finds no source files warns on stderr and asks whether you are in the project root.
pip install -U code-review-graph     # or: pipx upgrade / uv tool upgrade code-review-graph
code-review-graph doctor             # every copy, MCP entry and hook, and the version each runs
code-review-graph install --dry-run  # see what changes, then run install
code-review-graph build              # once: new file types and fixes reach only re-parsed files
Upgrade every copy you have. The MCP entry, the git and editor hooks and crg-daemon can each run a different one, and once 2.4.0 or later has opened the graph, a 2.3.9 copy refuses it and an older 2.3.x copy can break it. Run install again so the entry and the hooks run the new copy, then restart the editor (and run crg-daemon restart if you use the daemon).
The first command of 2.4.0 or later moves the graph to schema 15. If you use the VS Code extension, it needs version 0.4.0 to read that graph. Full list: upgrade notes.
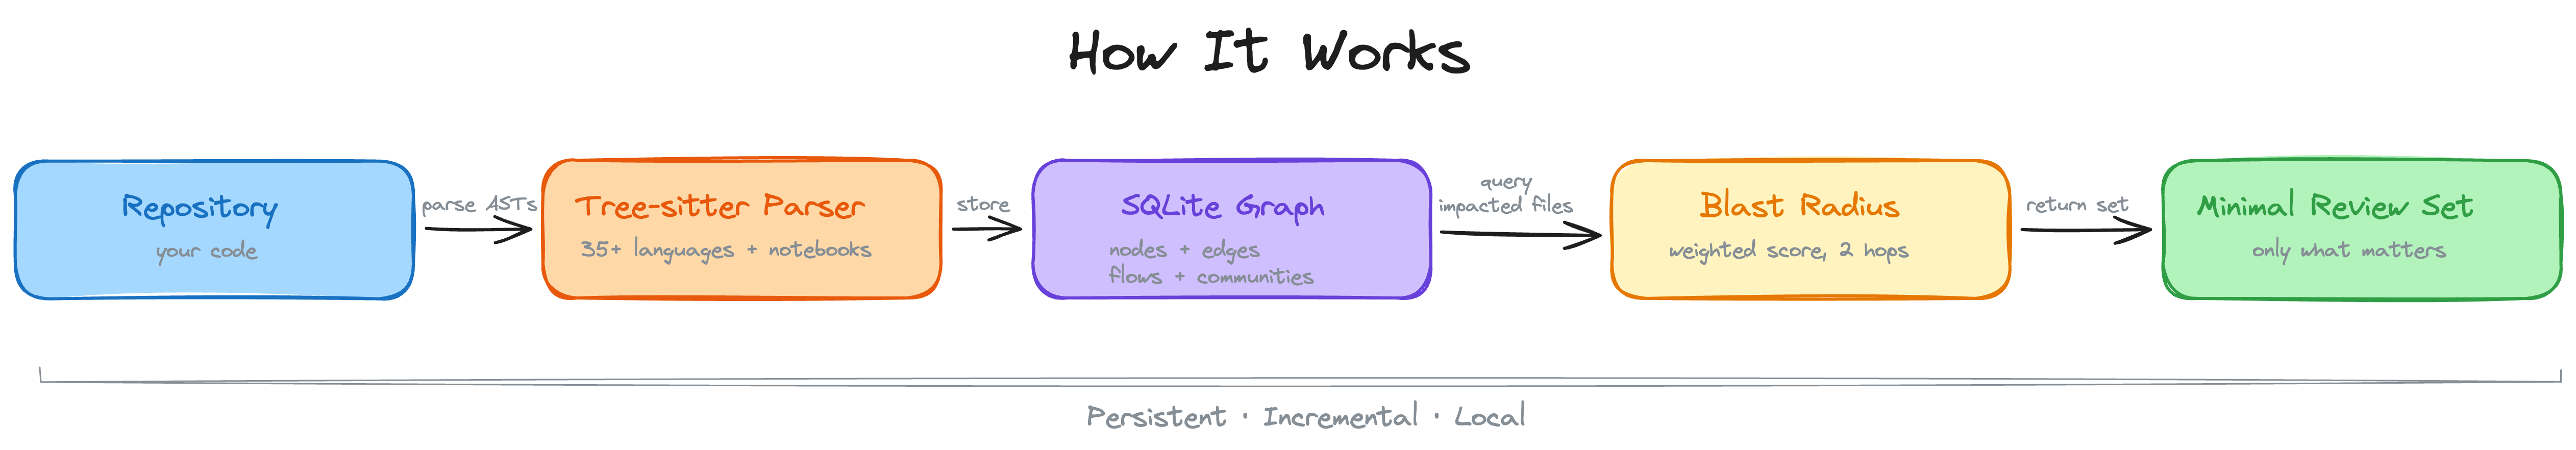
The repository is parsed into ASTs with Tree-sitter and stored as a graph of nodes (functions, classes, imports) and edges (calls, inheritance, test coverage). At review time the graph is queried for the smallest set of files the assistant needs to read.
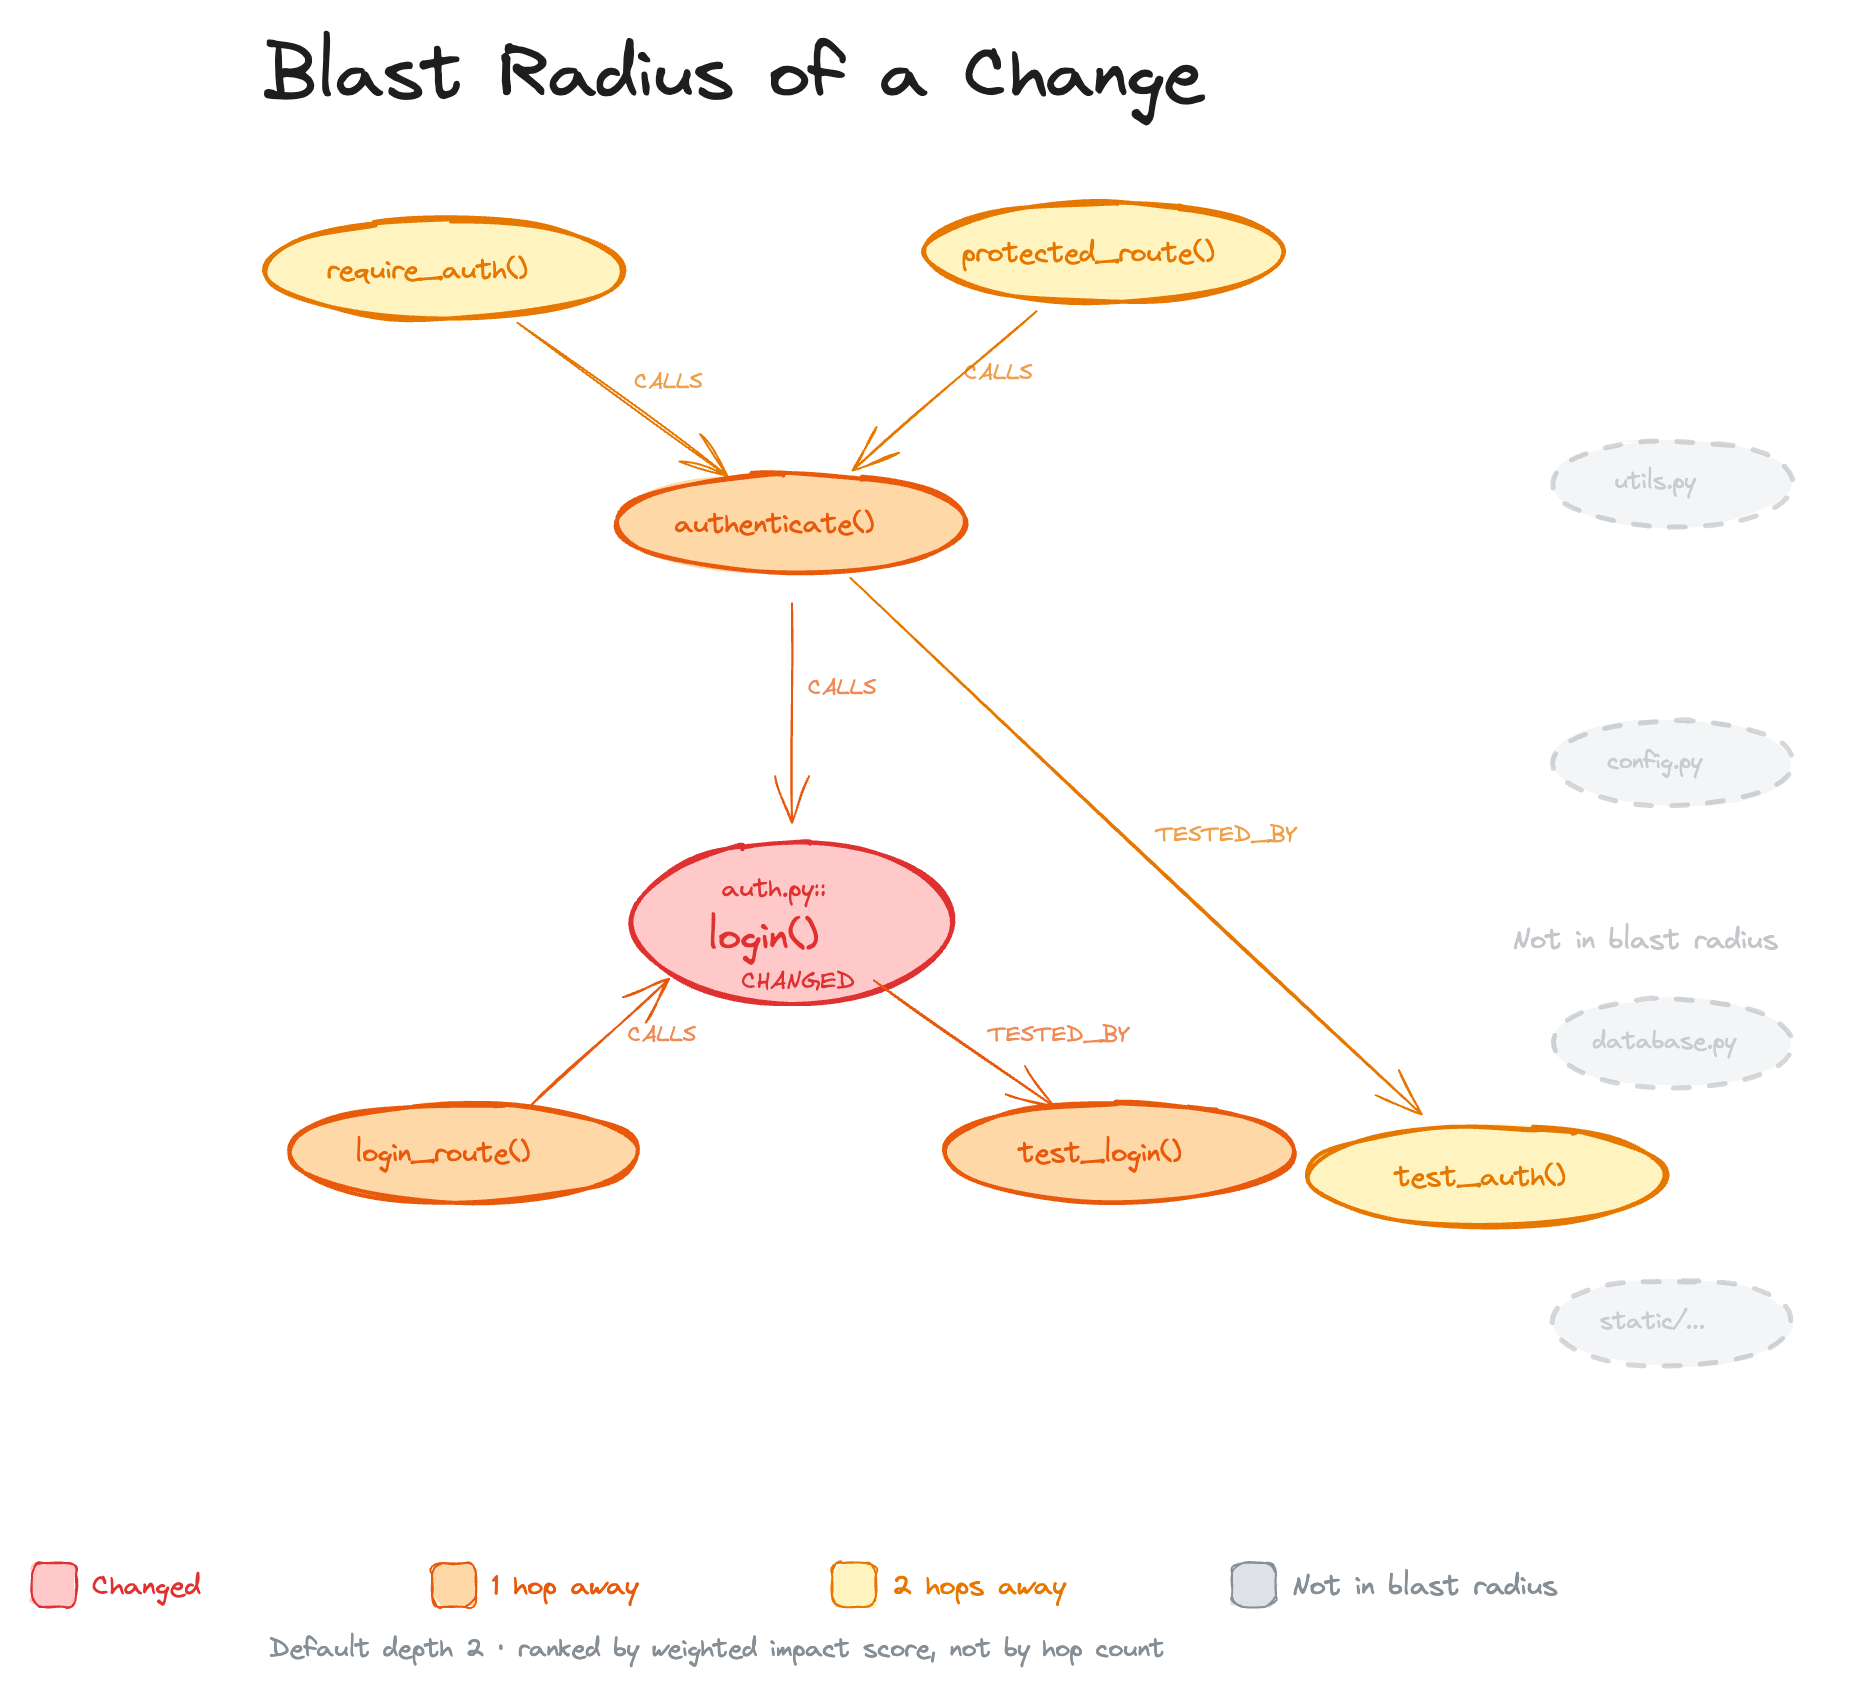
When a file changes, the graph traces every caller, dependent and test that could be affected. The assistant reads those files instead of scanning the whole project.
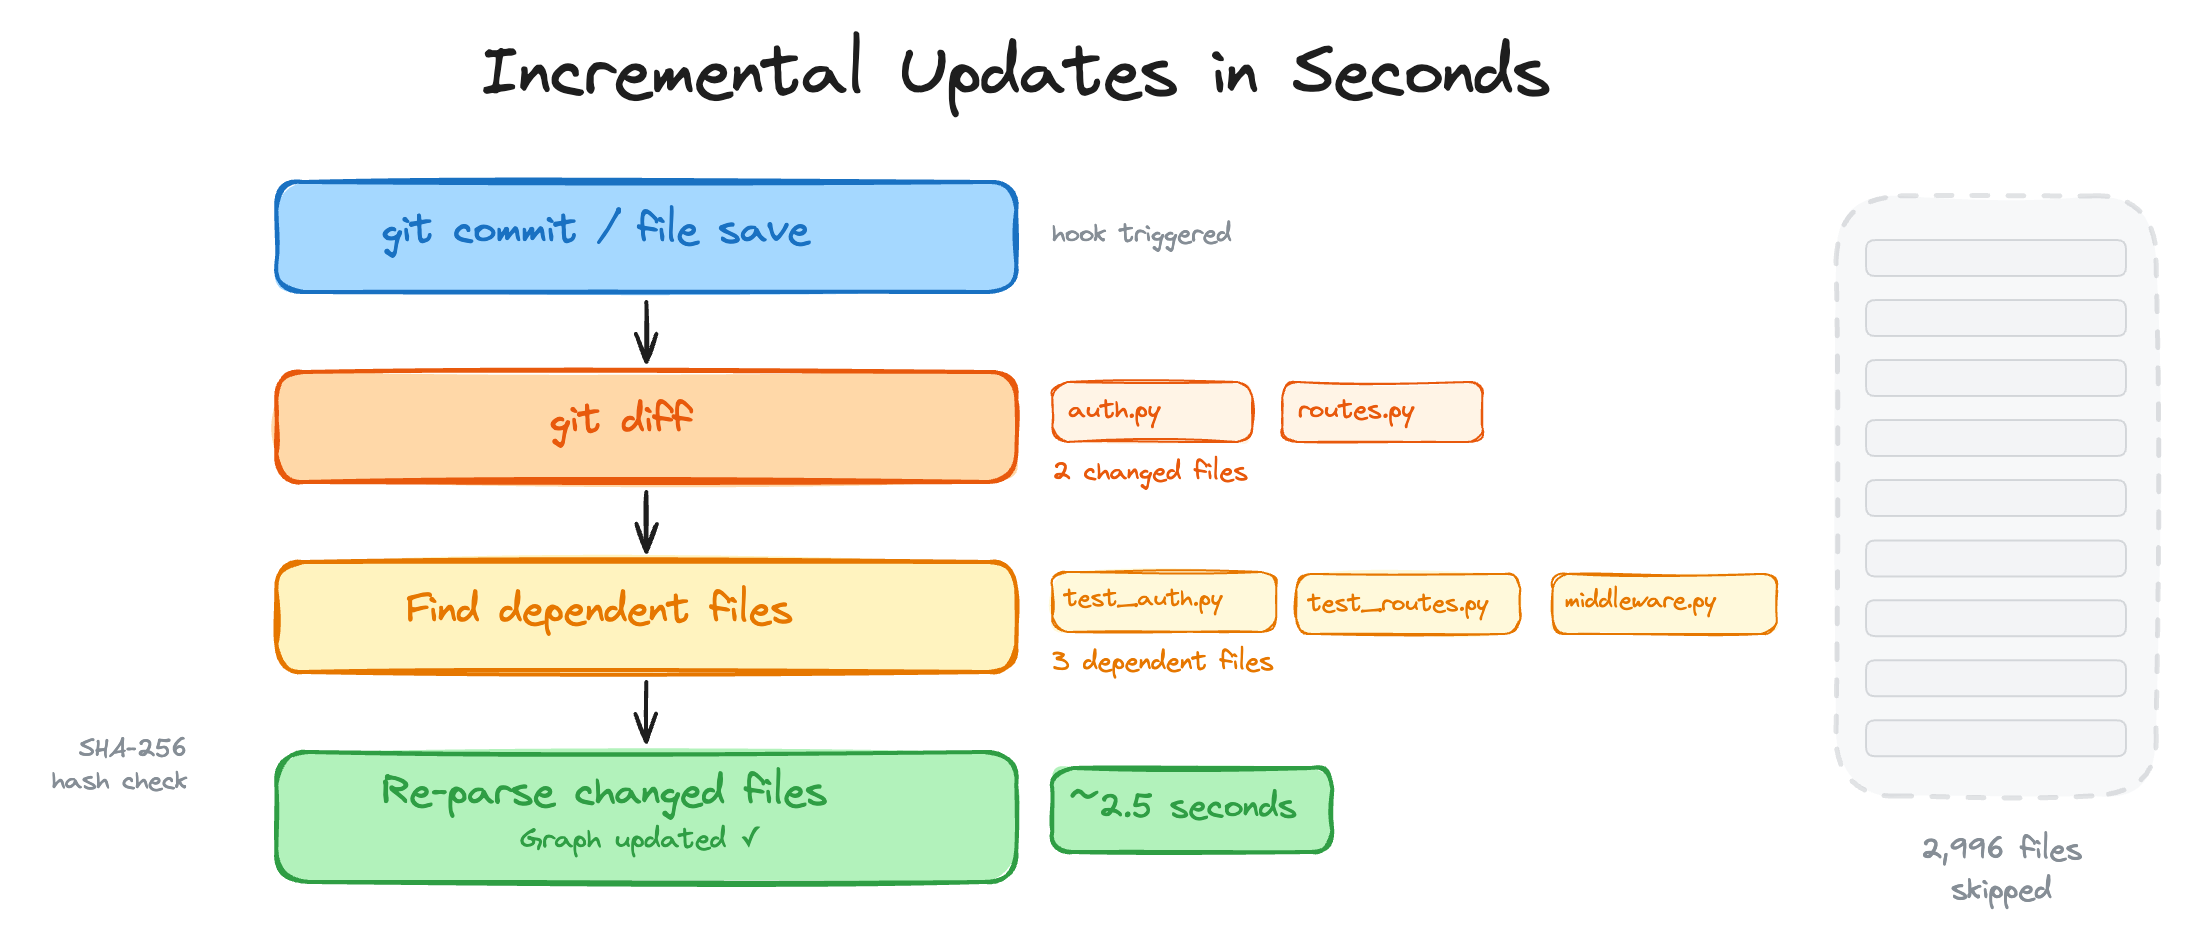
Editor hooks, git hooks (pre-commit, post-checkout, post-merge, post-rewrite) and watch mode trigger incremental updates. The hooks update quietly; on each commit the pre-commit hook prints only the short review from detect-changes --brief. The update diffs changed files, finds their dependents through the graph's import and call edges, and re-parses only the files whose SHA-256 hash changed. On a ~3,000-file project (django) a two-file edit re-indexes in about 2.5 seconds on the path the hooks use, of which ~1.4 s is process start-up; a no-op update costs only that start-up. See Incremental update latency.
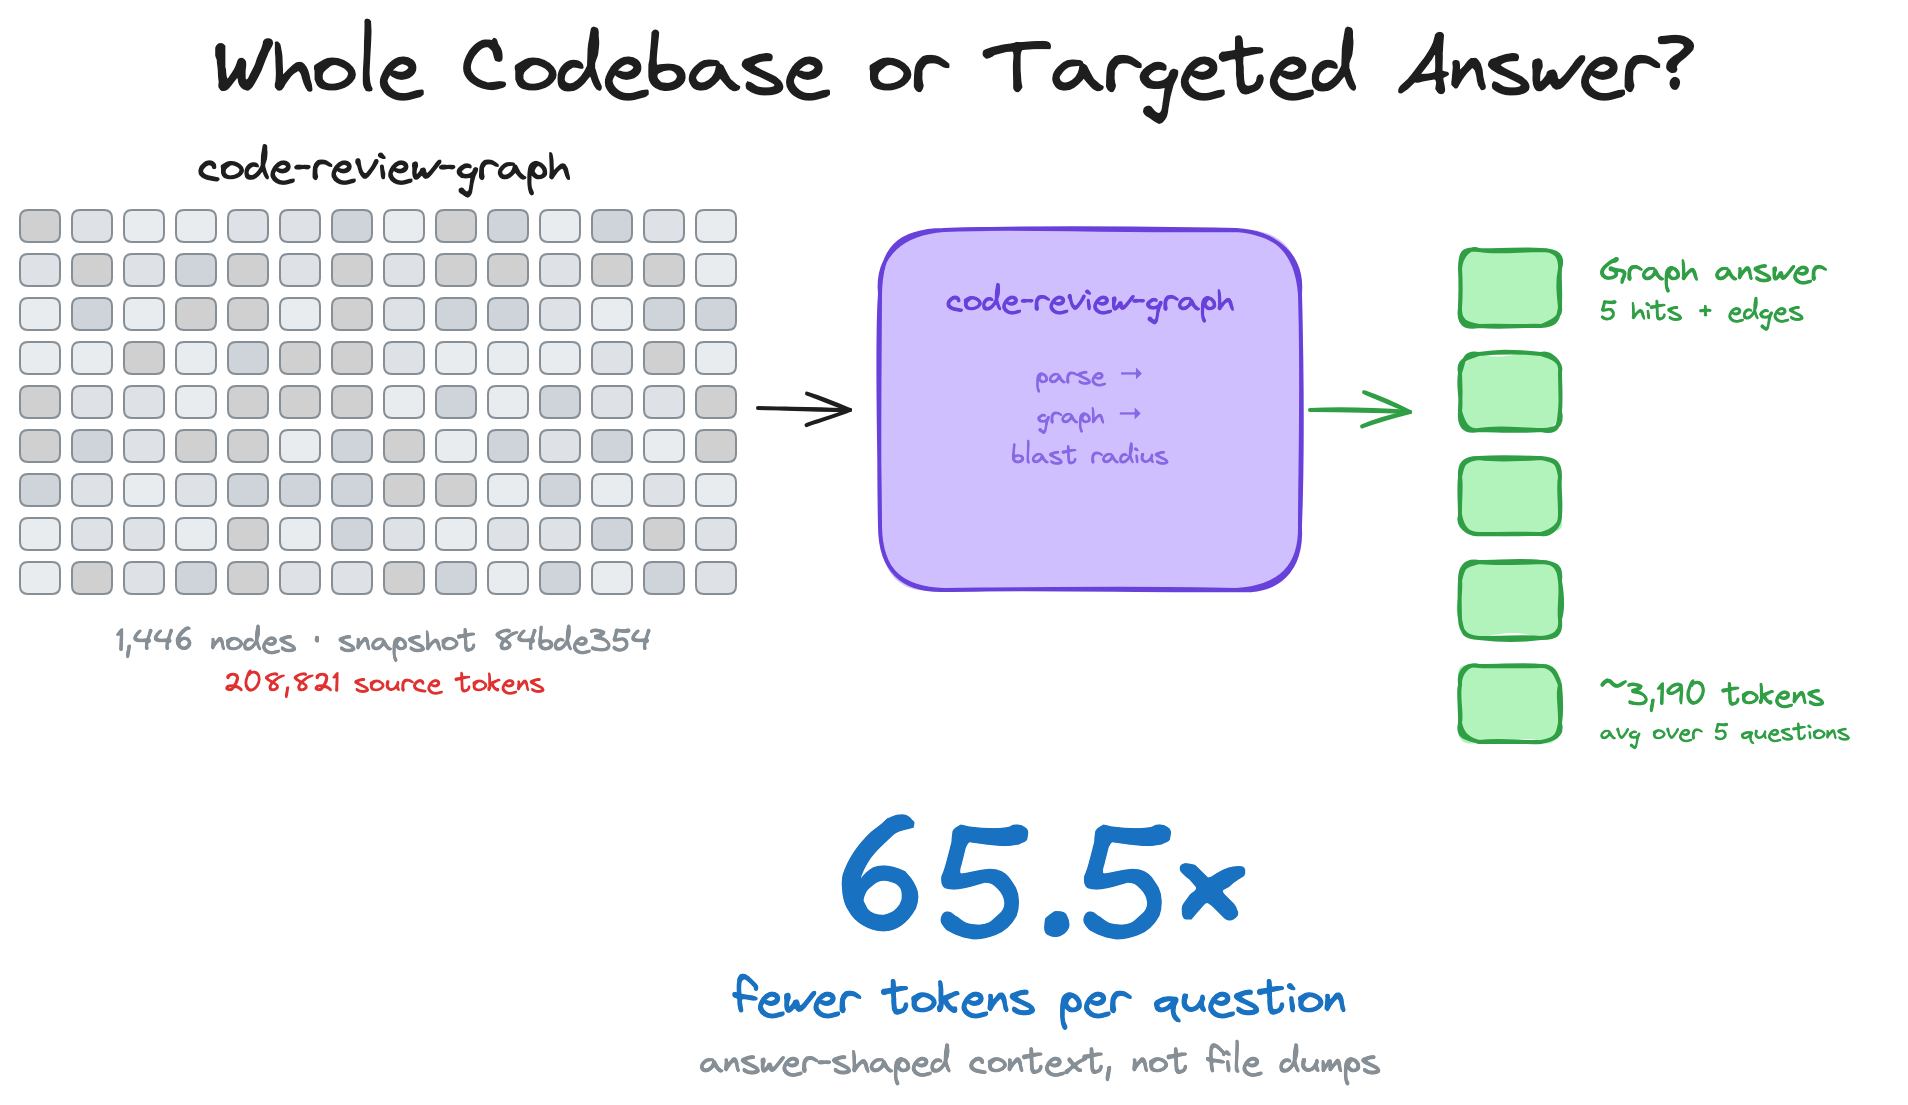
Instead of feeding a whole corpus to the model, the graph returns a slice shaped to the question. In the 2026-08-02 capture of this repository at 84bde354, 208,821 source tokens became ~3,190 tokens per question. The repository has grown a lot since that snapshot, so both numbers are larger today.
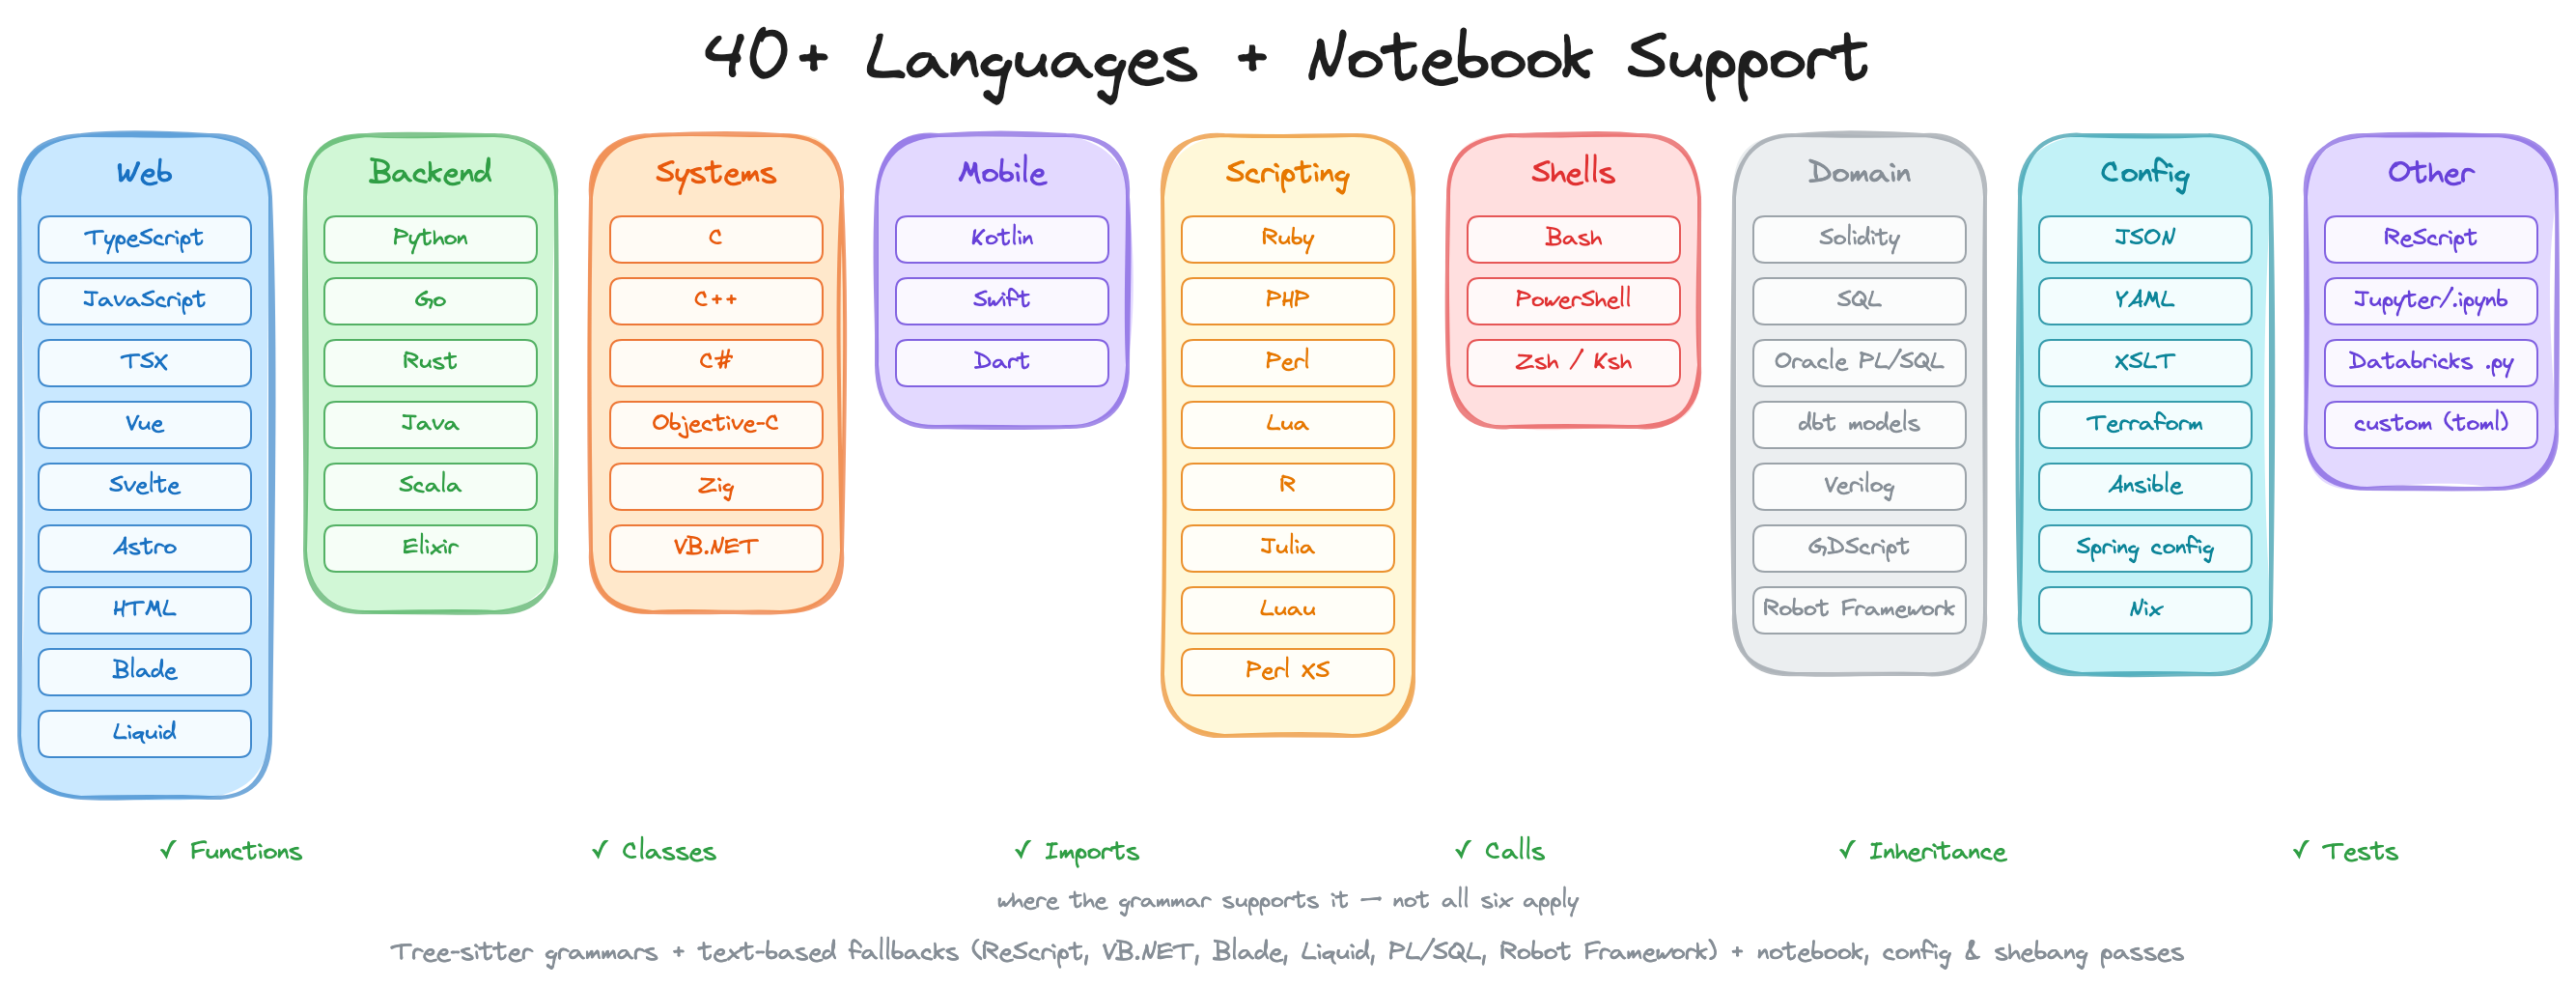
The parser extracts functions, classes, imports, call sites, inheritance and tests, using Tree-sitter where a grammar exists and targeted fallbacks elsewhere. Supported: Python, JavaScript/TypeScript/TSX (including .mjs, .cjs, .mts and .cts), Go, Rust, Java, C/C++, C#, VB.NET, Ruby, Kotlin (.kt, .kts), Swift, PHP, Scala, Solidity, Dart, R, Perl, Lua/Luau, Objective-C, shell scripts, Elixir, Zig, PowerShell, Julia, ReScript, GDScript, Nix, Verilog/SystemVerilog, SQL/PL/SQL (Oracle) and dbt models, Terraform/OpenTofu (.tf, and Terraform blocks in .hcl files; an .hcl file with no Terraform blocks keeps only a file node), Ansible YAML (playbooks, roles, tasks), Spring Boot application config (application.properties, application.yml, application.yaml and their application- variants; key names and value types only, never values), value-free generic YAML structure (translation files in folders such as locales/ become file nodes only), XSLT stylesheets (.xsl, .xslt), value-free JSON structure (.json; translation, test, docs, example and data files keep only a file node, and lock files are skipped), Vue/Svelte SFCs, HTML pages (.html, .htm; inline scripts, plus div, section and article blocks with an id as DocSection nodes), Astro files (parsed with the TypeScript grammar), Jupyter and Databricks notebooks (.ipynb, plus Databricks .py exports), Perl XS files (.xs), Robot Framework files (.robot, .resource), and Liquid templates (.liquid). Other .properties files are not treated as source code.
PHP projects also get repository-bounded Composer PSR-4 resolution, Blade template references,
and Laravel Route and Eloquent edges when the source shows explicit framework imports, model
inheritance and receiver evidence. Static Laravel routes in routes/*.php emit Endpoint nodes
and controller HANDLES edges, including literal group prefixes.
Java projects get Spring dependency-injection call resolution, request endpoints and WebFlux routes, scheduled triggers, application-event publisher-to-listener edges, Spring AOP advice-to-target edges, and Temporal workflow and activity edges. Each resolver runs after the parse and needs the injected field, published event or workflow stub to be visible in the repository.
languages.tomlIf your repository uses a language the parser does not cover, add a languages.toml to .code-review-graph/ that maps file extensions to any grammar bundled in tree_sitter_language_pack, plus the node types for functions, classes, imports and calls:
[languages.erlang]
extensions = [".erl"]
grammar = "erlang"
function_node_types = ["function_clause"]
class_node_types = ["record_decl"]
import_node_types = ["import_attribute"]
call_node_types = ["call"]
The generic tree-sitter walker does the extraction. Built-in languages cannot be overridden. See docs/CUSTOM_LANGUAGES.md for the schema, validation rules and a worked example.
The same analysis runs as a composite GitHub Action. The graph is built and queried on your CI runner; no source code is sent to an external service. On each pull request the action posts one sticky comment with risk-scored functions, affected execution flows and test gaps, updated in place on every push. The optional fail-on-risk input turns it into a merge gate. The optional details input adds more graph context, folded away and capped in size: why each top symbol scored what it did, the communities, hubs and cross-boundary links the change touches, its impact radius, its untested hotspots, and where the graph came from.
# .github/workflows/code-review-graph.yml
on:
pull_request:
permissions:
contents: read
pull-requests: write
jobs:
review:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v7
- uses: tirth8205/code-review-graph@v2.4.0
with:
github-token: ${{ secrets.GITHUB_TOKEN }}
See docs/GITHUB_ACTION.md for inputs, risk levels and caching, or the workflow this repository runs on itself in .github/workflows/pr-review.yml.
---
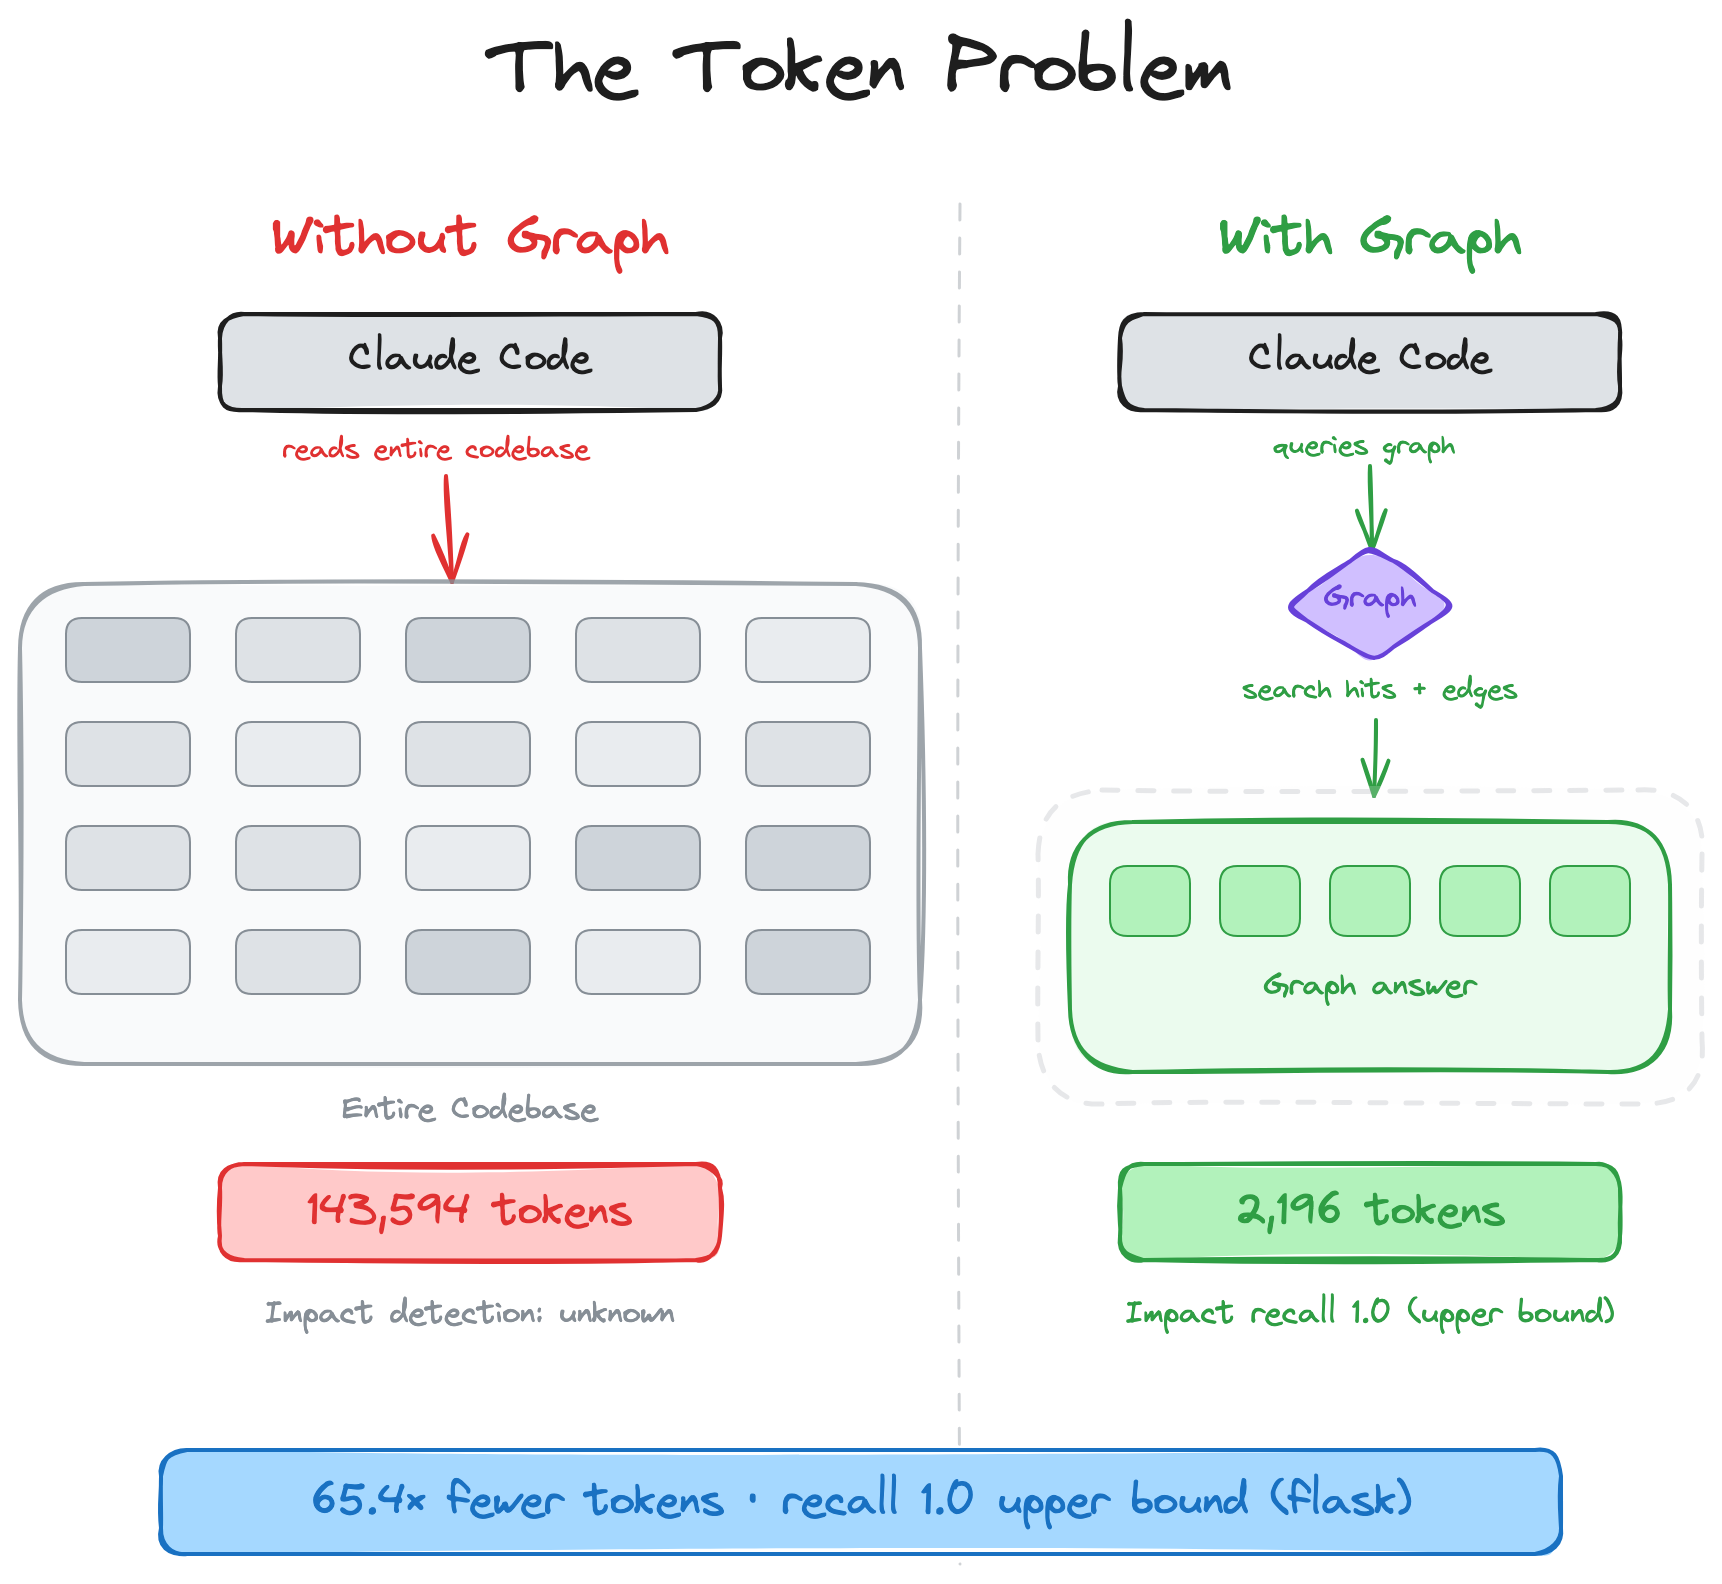
The median per-question token reduction across the 6 repositories is about 63x (whole-corpus baseline vs graph query). The 358x maximum is one repository (fastapi, the largest corpus), not the typical result.
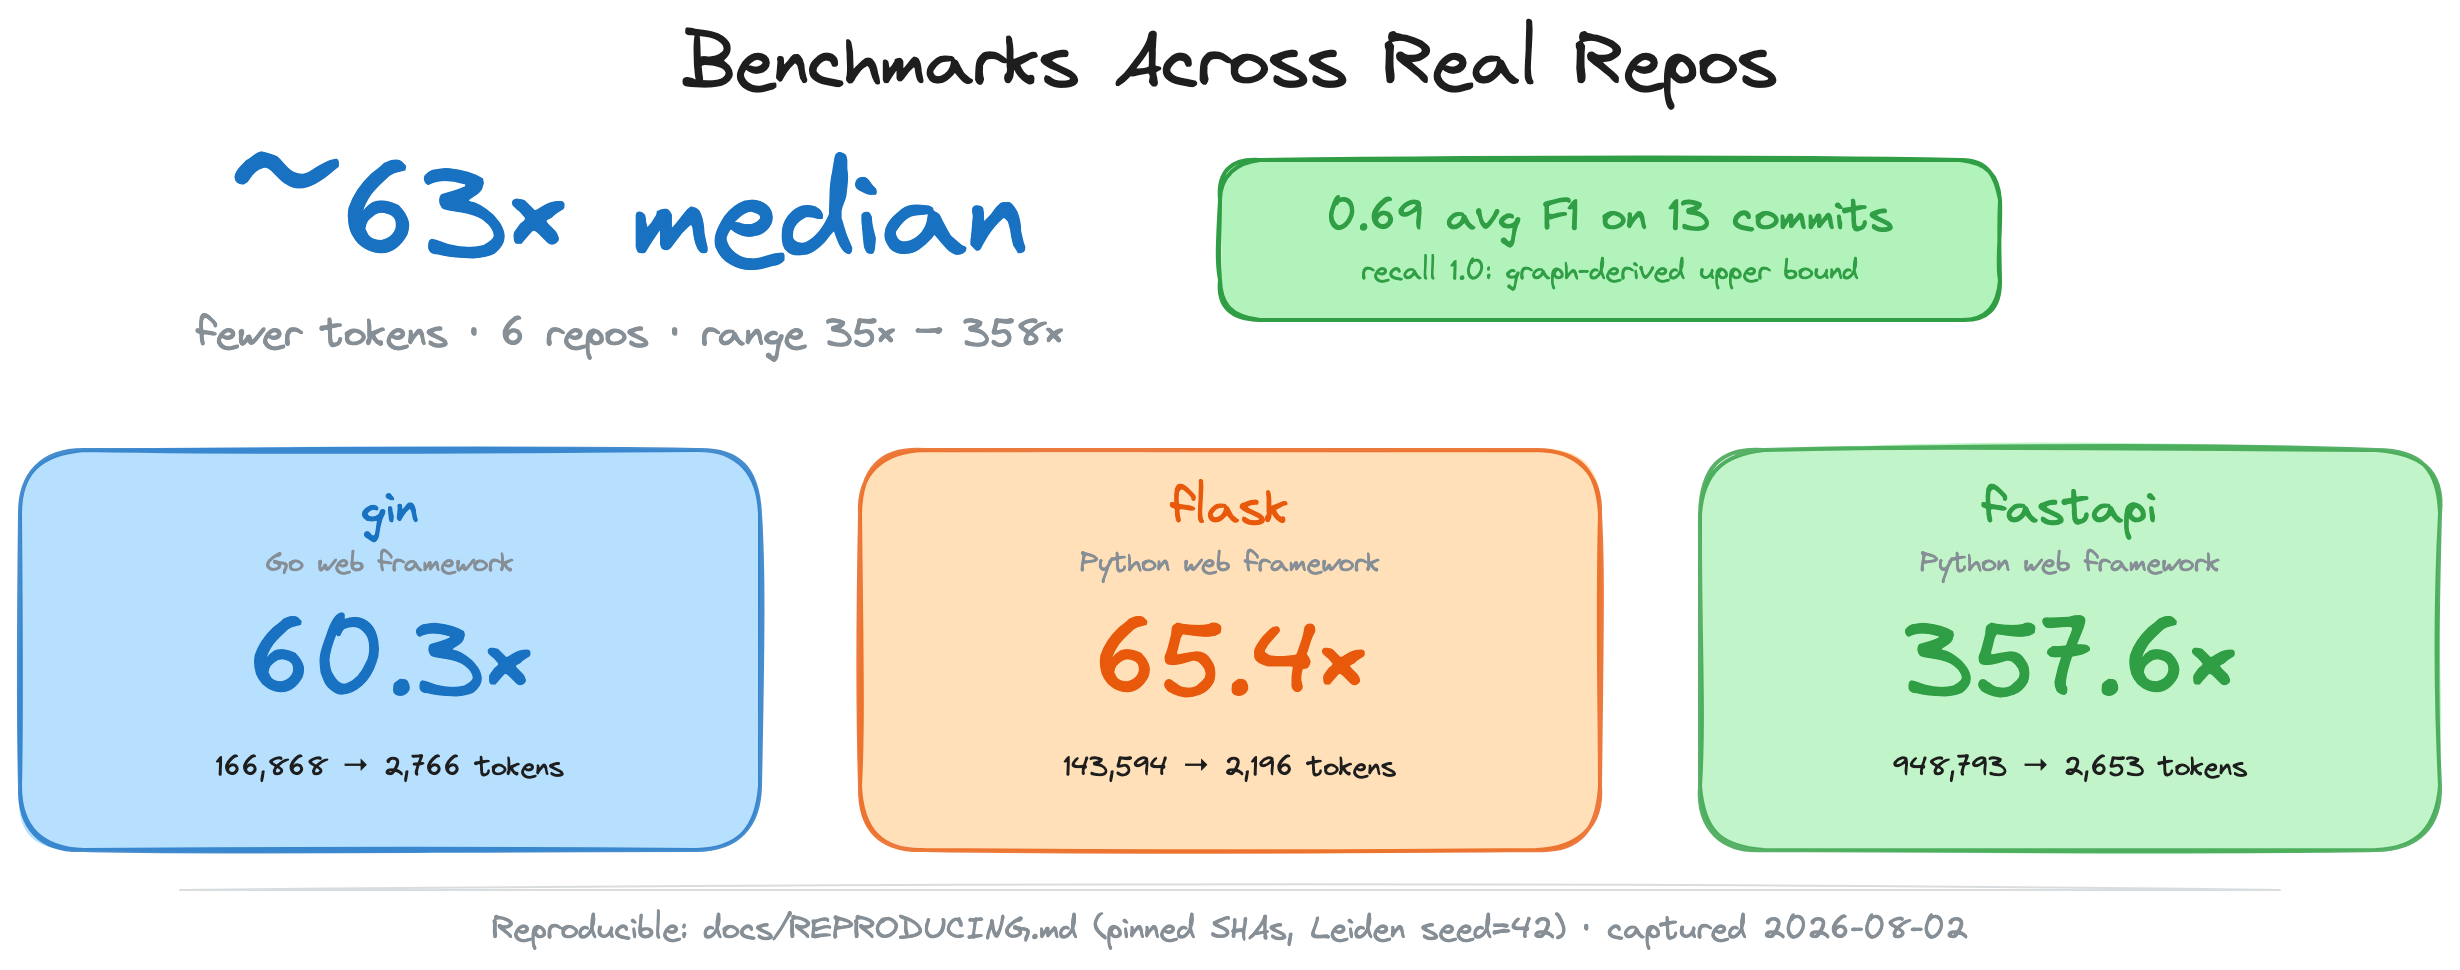
All numbers come from the evaluation runner against 6 open-source repositories (13 commits). Every config pins an upstream SHA, Leiden runs with a fixed seed, and embeddings are deterministic on CPU, so two runs on different machines produce the same numbers. The reproduction recipe is in docs/REPRODUCING.md. A weekly report-only run on the two smallest configs lives in .github/workflows/eval.yml.
For a typical agent question ("how does authentication work", "what is the main entry point", and so on), the graph returns ~2,200 to 3,900 tokens of search hits plus neighbour edges instead of every source file. The table averages the 5 sample questions defined in code_review_graph/token_benchmark.py.
| Repo | Snapshot SHA | naive_corpus_tokens | avg graph_tokens | Reduction |
|------|---|-----------------:|----------------:|----------:|
| fastapi | 22381558 | 948,793 | 2,653 | 357.6x |
| flask | a29f88ce | 143,594 | 2,196 | 65.4x |
| code-review-graph | 84bde354 | 208,821 | 3,190 | 65.5x |
| gin | 5c00df8a | 166,868 | 2,766 | 60.3x |
| httpx | b55d4635 | 142,356 | 2,661 | 53.5x |
| express | b4ab7d65 | 136,052 | 3,936 | 34.6x |
Captured 2026-08-02 from clean clones at the pinned SHAs (crg 2.3.7, localall-MiniLM-L6-v2embeddings). These numbers are lower than the 2026-05-25 capture they replace: node embedding text became richer, soavg graph_tokensrose in every repo. fastapi is measured at its current pin22381558rather than the retired0227991a.
> The Reduction column isnaive_corpus_tokens / avg graph_tokens, so it divides out from the two columns beside it. The benchmark's ownaverage_reduction_ratioaverages the five per-question ratios instead, which always reads higher; those per-question figures are indocs/REPRODUCING.md.
> Thecode-review-graphrow is a snapshot, not a current measurement. The repository has grown since84bde354, so its corpus and graph are both much larger today.
The whole-corpus baseline is an upper bound no real agent pays; an agent greps for identifiers and reads the best-matching files. The agent_baseline eval benchmark measures that case (a pure-Python grep over the corpus, top-3 files by match count, token-counted against the graph query cost). Against that realistic baseline the median across 18 questions on 6 repositories is 6.65x (mean 14.8x, range 4.2x to 72.6x), captured 2026-09-22, before search and this baseline began ranking test files lower, so code-review-graph eval --benchmark agent_baseline --embed now gives different numbers until the capture is redone. The full table is in docs/REPRODUCING.md, under "Canonical capture, 2026-09-22".
The ratio tracks repository size, because the graph answer stays flat (2,432 to 4,021 tokens across every repo measured) while the grep baseline grows with the corpus: 4.5x on express, 52x on fastapi. Both figures measure retrieval cost, the tokens needed to locate an answer. An agent that then opens the files the graph named pays the graph on top of its usual reads rather than instead of them; semantic_search_nodes_tool(include_source=True) returns the code with the locations so it does not have to, and measuring that path end-to-end is open work.
The formal token_efficiency benchmark measures a different scenario, the full get_review_context() JSON against only the changed-file content of a commit, and reports ratios below 1 for small commits because the response carries impact-radius edges and source snippets. The two benchmarks answer different questions; see docs/REPRODUCING.md.
Review and impact tools attach a compact context_savings estimate to their responses. The CLI shows the same figures in the Token Savings panel (see Usage below) and --verify compares them with OpenAI's cl100k_base tokenizer. Calibration across 222 sample files puts the estimate within about 1% of real tokens in aggregate (data).
Blast-radius analysis recovers every file in the ground truth on all 13 evaluation commits. Read that as an upper bound, not as "100% recall": the ground truth (changed files plus files with call or import edges into them) comes from the same graph the predictor traverses. The lower precision is deliberate; flagging an extra file costs less than missing a broken dependency.
| Repo | Commits | Avg F1 | Avg Precision | Recall (graph
→ →
 →
 →
 →
 →
 →
 →