1
 →
An open-source long-horizon SuperAgent harness that researches, codes, and creates. With the help of sandboxes, memories, tools, skill, subagents and message gateway
bytedance/deer-flow is an open-source project on GitHub, mainly written in Python. An open-source long-horizon SuperAgent harness that researches, codes, and creates. It currently holds 82,744 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
Git Homed tracks it on the AI Agent Skills Trending board and on the AI AI Agent Skills Trending list.
English | 中文 | 日本語 | Français | Русский


On February 28th, 2026, DeerFlow claimed the 🏆 #1 spot on GitHub Trending following the launch of version 2. Thanks a million to our incredible community — you made this happen! 💪🔥
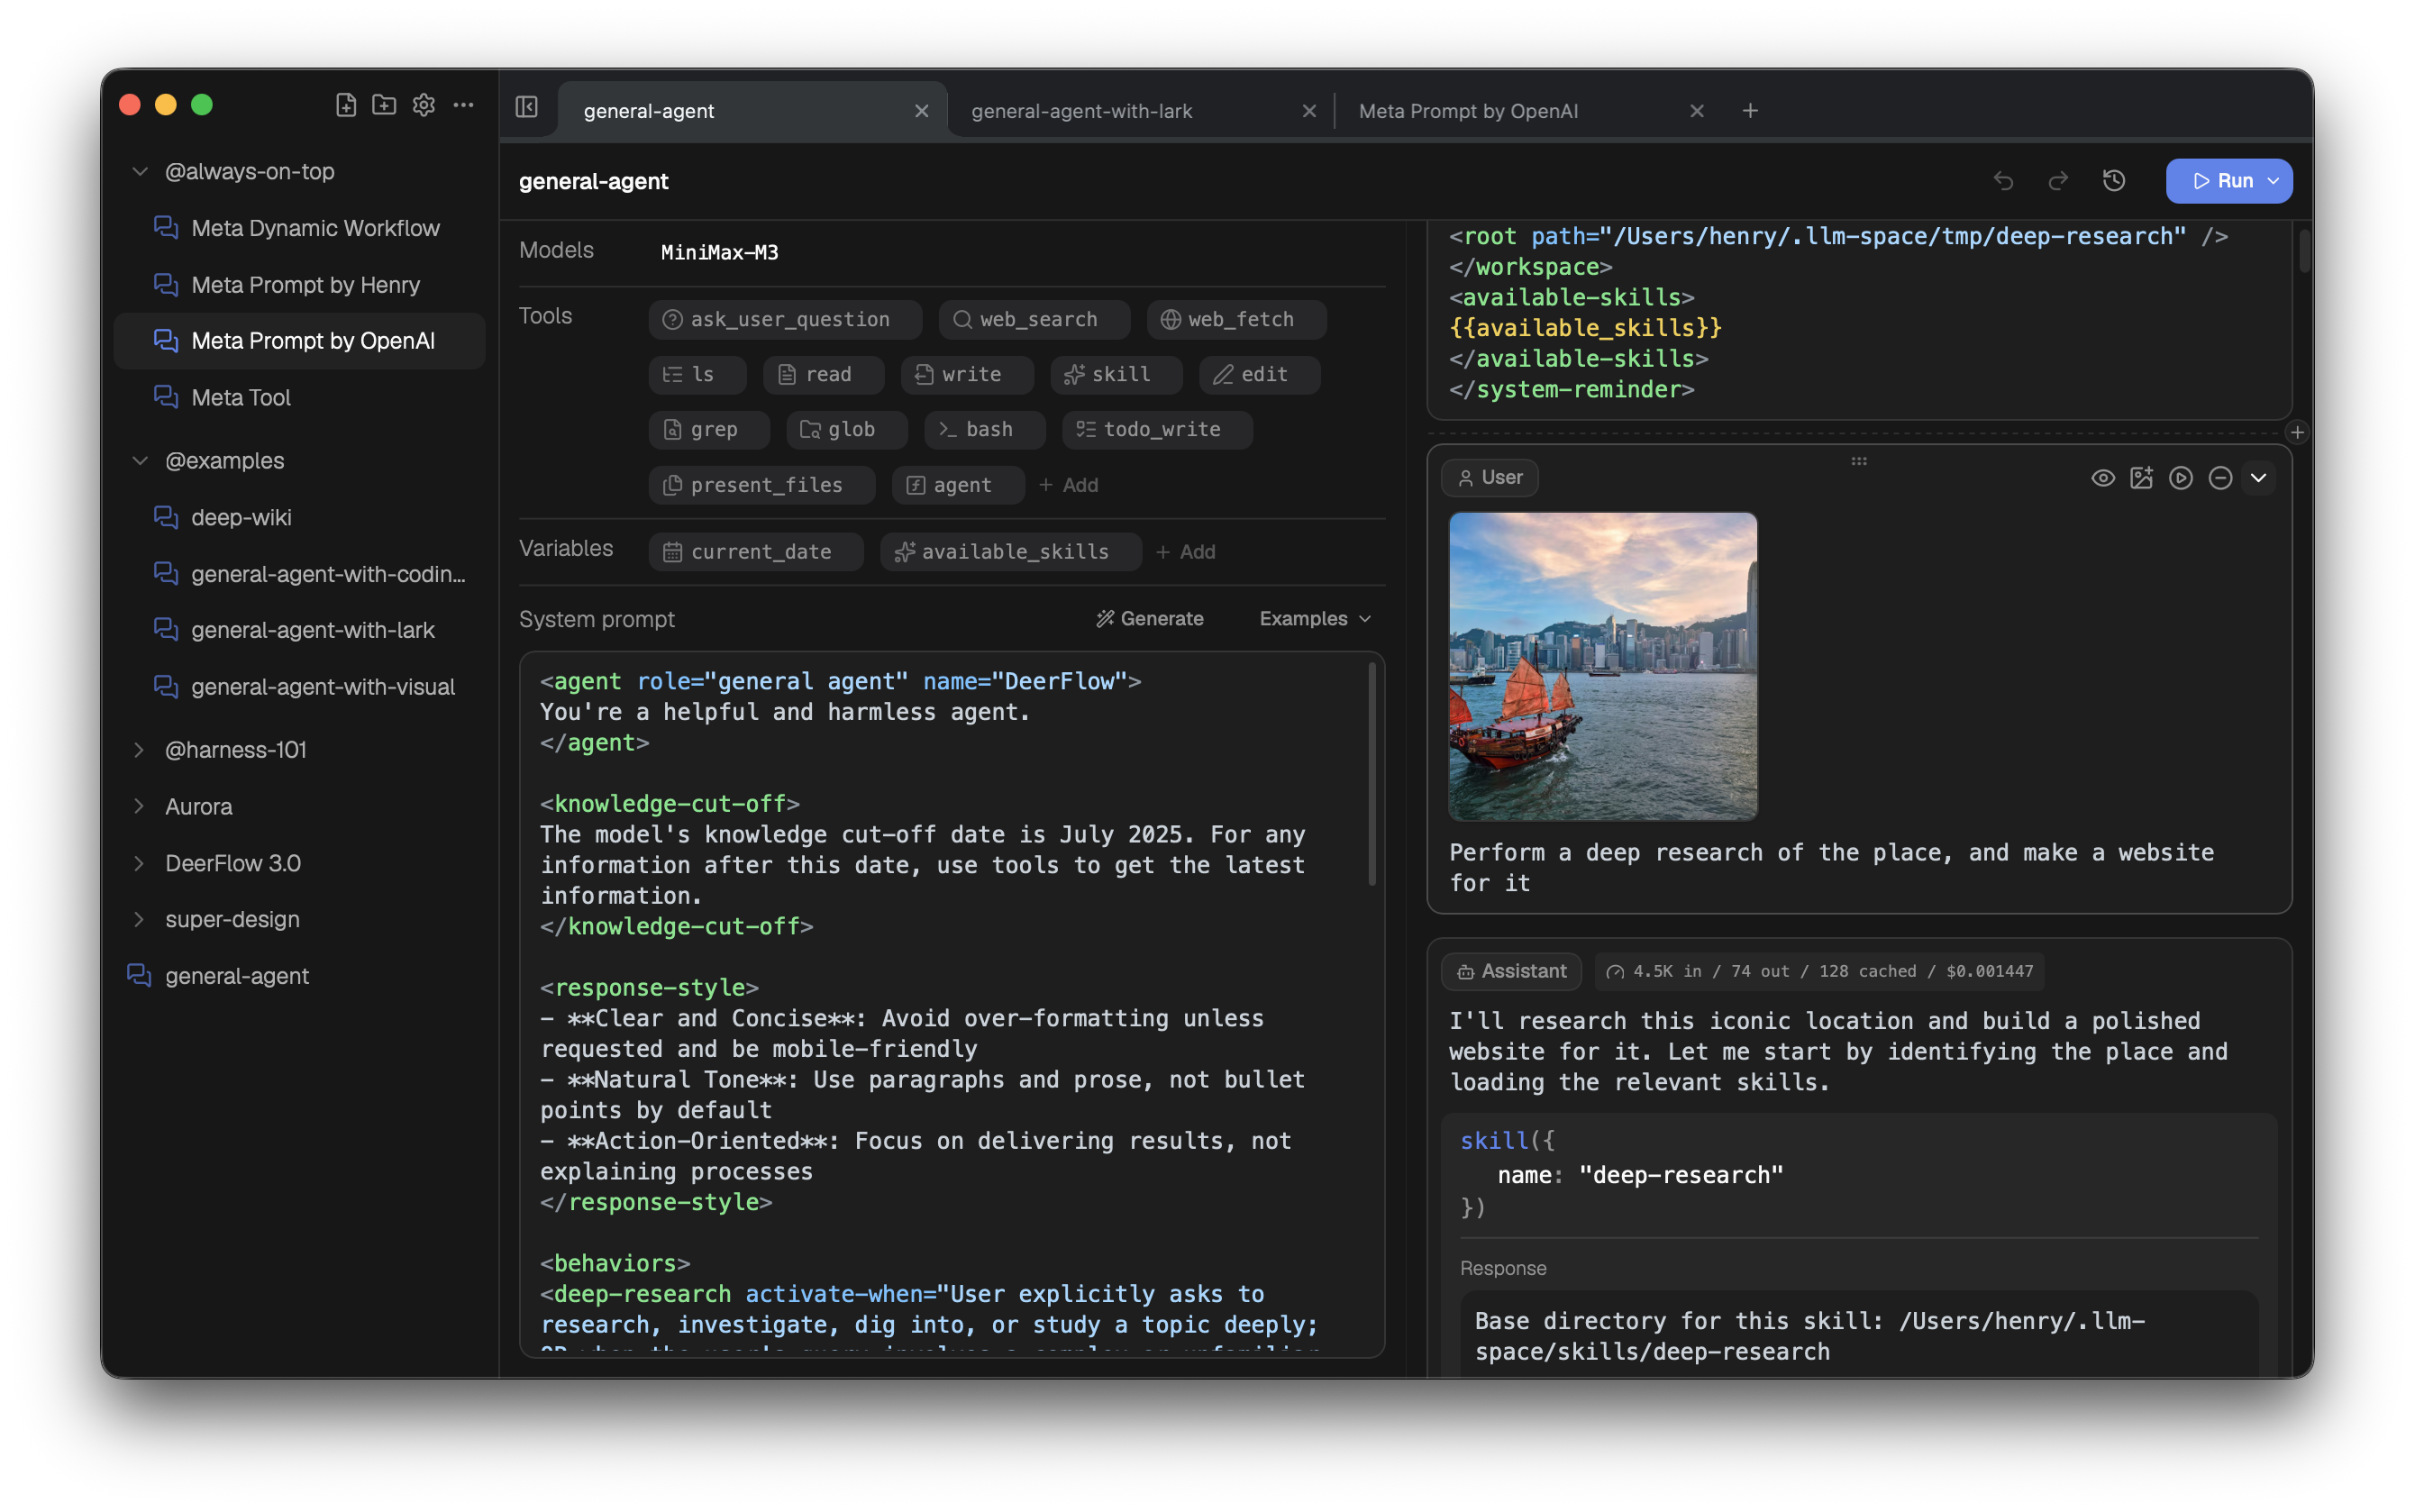
DeerFlow (Deep Exploration and Efficient Research Flow) is an open-source super agent harness that orchestrates sub-agents, memory, and sandboxes to do almost anything — powered by extensible skills.
https://github.com/user-attachments/assets/a8bcadc4-e040-4cf2-8fda-dd768b999c18
[!NOTE]
DeerFlow 2.0 is a ground-up rewrite. It shares no code with v1. If you're looking for the original Deep Research framework, it's maintained on the 1.x branch — contributions there are still welcome. Active development has moved to 2.0.
Learn more and see real demos on our official website. The landing-page case studies open as allowlisted, read-only showcases without requiring a sign-in.
InfoQuest reader, web search, and image search use a 30-second HTTP connect/read
inactivity timeout. The crawl timeout and navigation_timeout settings remain
separate server-side options; they do not control the local HTTP timeout.
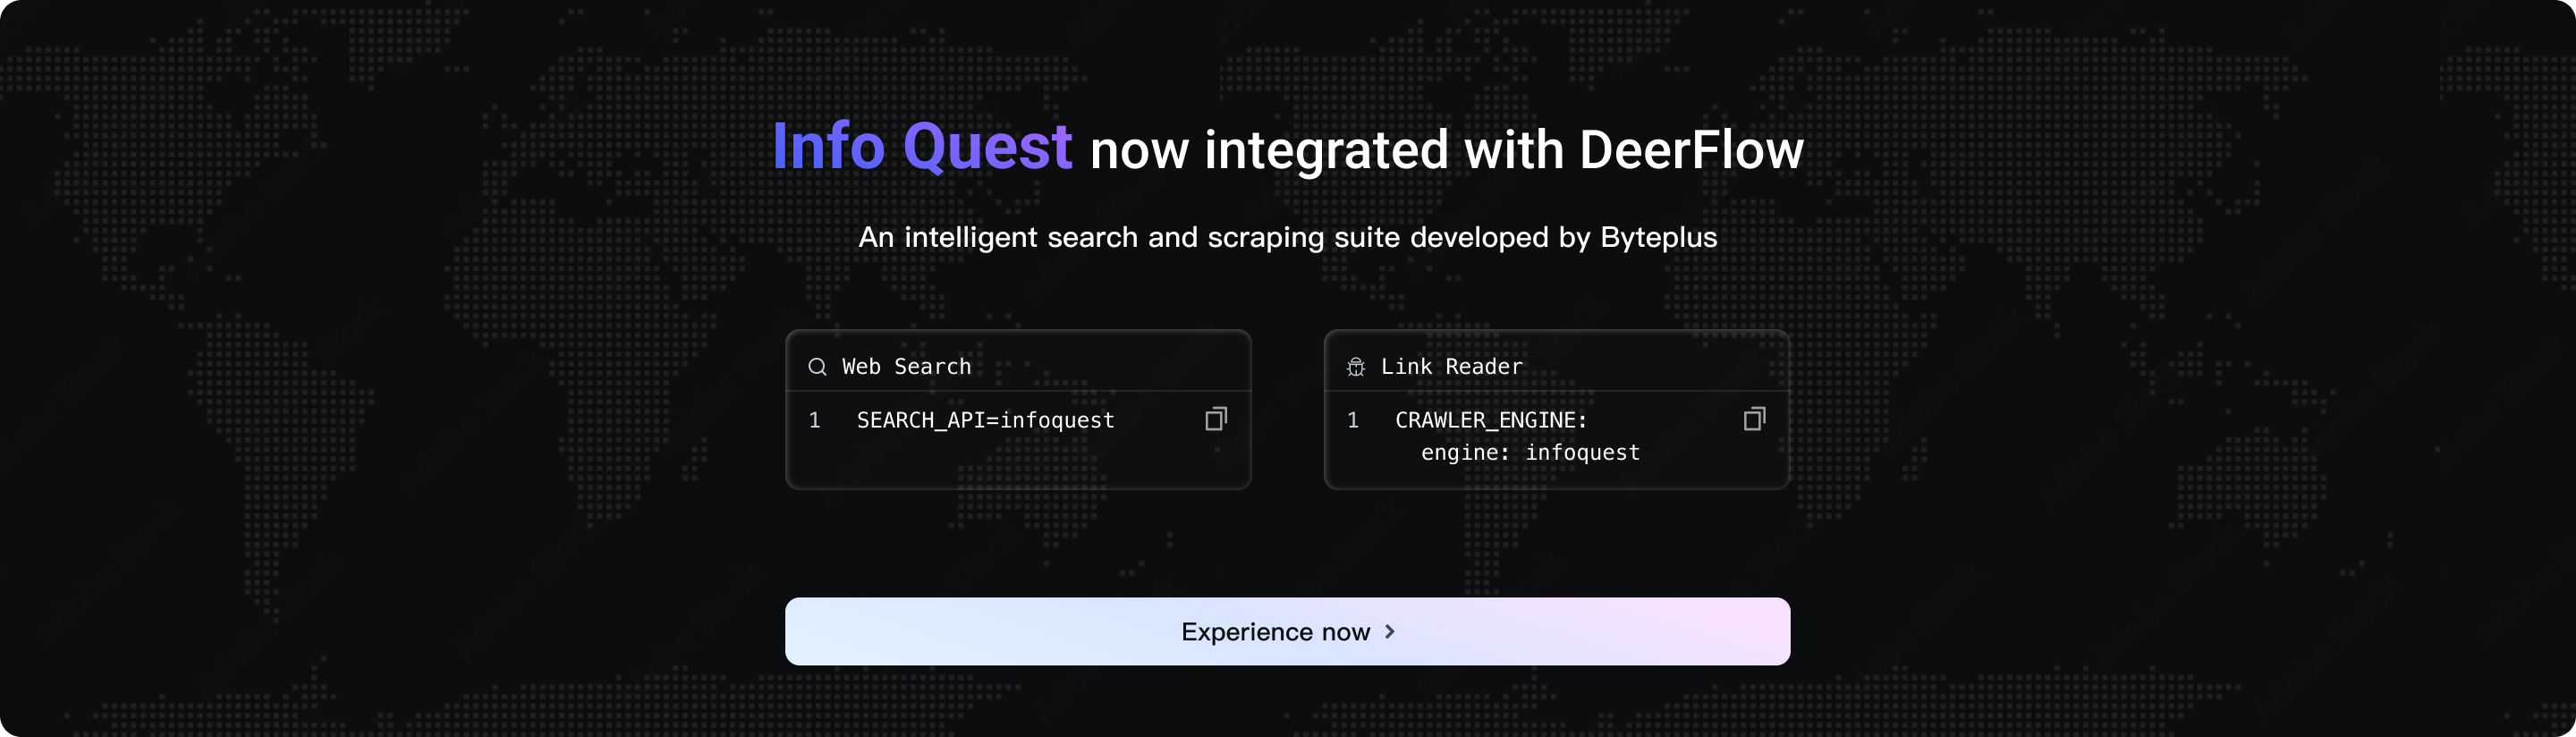
DeerFlow has newly integrated the intelligent search and crawling toolset independently developed by BytePlus--InfoQuest (supports free online experience)
---
If you use Claude Code, Codex, Cursor, Windsurf, or another coding agent, you can hand it the setup instructions in one sentence:
Help me clone DeerFlow if needed, then bootstrap it for local development by following https://raw.githubusercontent.com/bytedance/deer-flow/main/Install.md
That prompt is intended for coding agents. It tells the agent to clone the repo if needed, choose Docker when available, and stop with the exact next command plus any missing config the user still needs to provide.
Optional per-model request_admission
paces requests to help stay within provider request-per-minute limits.
It is disabled by default; see the linked guide to enable it.
1. Clone the DeerFlow repository
   git clone https://github.com/bytedance/deer-flow.git
   cd deer-flow
2. Run the setup wizard
From the project root directory (deer-flow/), run:
make setup
This launches an interactive wizard that guides you through choosing an LLM provider, optional web search, and execution/safety preferences such as sandbox mode, bash access, and file-write tools. It generates a minimal config.yaml and writes your keys to .env. Takes about 2 minutes.
The wizard also lets you configure an optional web search provider, or skip it for now.
Jina, Browserless, and InfoQuest web fetches resolve relative links and image sources using the requested page URL (or a usable HTML base URL), so returned Markdown includes complete destinations. Link resolution preserves the surrounding HTML source, including malformed-page formatting.
Run make doctor at any time to verify your setup and get actionable fix hints.
If you are opening a GitHub issue about a local setup or runtime problem, run
make support-bundle. The command prints reporter next steps, writes a
-issue-summary.md file to paste into the issue, a -issue-draft.md file
for AI-assisted issue filing, and an optional evidence zip under
.deer-flow/support-bundles/. If an AI assistant files the issue, start from
the draft and replace every REQUIRED placeholder instead of inventing missing
facts. Attach the zip only if a maintainer asks for it, or if the summary
alone is not enough. Maintainers and AI triage tools can start with
triage.json; the bundle includes redacted diagnostics and file manifests
only, and does not include .env, raw conversation messages, or user file
contents.
> Advanced / manual configuration: If you prefer to edit config.yaml directly, run make config instead to copy the full template. Optional dependency auto-detection accepts UTF-8 configuration files with or without a byte-order mark (BOM). See config.example.yaml for the complete reference including CLI-backed providers (Codex CLI, Claude Code OAuth), OpenRouter, Responses API, subagent runtime caps such as subagents.max_total_per_run, and more.
Optional per-model pricing must use one currency across all priced models. DeerFlow disables Console cost estimates when currencies are mixed rather than presenting an invalid aggregate.
Administrators can also open Settings → Models to add, edit, test, and
enable/disable shared OpenAI-compatible Chat Completions models without editing
config.yaml. Enter a unique name, base URL, model ID, and optional API key;
saving refreshes the chat model list. Connection testing sends a short streaming
tool-call request and may incur provider charges. It does not save the draft or
verify image support; set image support and token limits from provider documentation.
Native provider adapters and advanced reasoning settings remain YAML-configured.
YAML models remain read-only in this page and take precedence on name conflicts. Managed models are appended after YAML models; edits apply to new configuration snapshots, while active runs retain their existing snapshot. Disabling a model removes it from future selection/resolution, so update any custom-agent or scheduled task definitions that explicitly reference it before disabling it. Managed models are shared by the deployment, not personal API-key profiles, and remain subject to the existing model authorization policy.
The encrypted catalog and a generated local encryption key are stored in
$DEER_FLOW_HOME/managed-models/ (default .deer-flow/managed-models/). Persist
and back up the whole directory, restrict filesystem access, and share it
across Gateway workers/replicas that should use the same catalog. The local key
is protected by filesystem permissions; encryption does not protect against
someone who can read both files. Losing the key requires restoring the backup.
Reads and writes fail if the catalog cannot be decrypted, rather than replacing it.
This storage is independent of the SQL backend and works with read-only YAML mounts.
When several models are configured, open either model picker and use the star beside a model to favorite it. Favorites appear first in both the main chat and Side Chat pickers without changing either chat's selected or default model. They are stored for the signed-in user in the current browser, so they do not sync to another browser or device and do not require a startup setting. The compact favorites picker intentionally omits search and only adds favorite ordering to the two-line model list.
models:
- name: gpt-4o
display_name: GPT-4o
use: langchain_openai:ChatOpenAI
model: gpt-4o
api_key: $OPENAI_API_KEY
- name: openrouter-gemini-2.5-flash
display_name: Gemini 2.5 Flash (OpenRouter)
use: langchain_openai:ChatOpenAI
model: google/gemini-2.5-flash-preview
api_key: $OPENROUTER_API_KEY
base_url: https://openrouter.ai/api/v1
- name: gpt-5-responses
display_name: GPT-5 (Responses API)
use: langchain_openai:ChatOpenAI
model: gpt-5
api_key: $OPENAI_API_KEY
use_responses_api: true
output_version: responses/v1
- name: qwen3-32b-vllm
display_name: Qwen3 32B (vLLM)
use: deerflow.models.vllm_provider:VllmChatModel
model: Qwen/Qwen3-32B
api_key: $VLLM_API_KEY
base_url: http://localhost:8000/v1
supports_thinking: true
when_thinking_enabled:
extra_body:
chat_template_kwargs:
enable_thinking: true
OpenRouter and similar OpenAI-compatible gateways should be configured with langchain_openai:ChatOpenAI plus base_url. If you prefer a provider-specific environment variable name, point api_key at that variable explicitly (for example api_key: $OPENROUTER_API_KEY).
To route OpenAI models through /v1/responses, keep using langchain_openai:ChatOpenAI and set use_responses_api: true with output_version: responses/v1.
The setup wizard includes a Z.AI GLM-5.3-Flash profile. Because that model requires thinking and only accepts its own restricted effort levels, the compatibility profile keeps thinking enabled for every foreground and background call and temporarily suppresses DeerFlow's generic effort selector. See config.example.yaml for the equivalent manual configuration.
For vLLM 0.19.0, use deerflow.models.vllm_provider:VllmChatModel. For Qwen-style reasoning models, DeerFlow toggles reasoning with extra_body.chat_template_kwargs.enable_thinking and preserves vLLM's non-standard reasoning field across multi-turn tool-call conversations. Legacy thinking configs are normalized automatically for backward compatibility. If the endpoint reports a cumulative usage snapshot on every streaming chunk, set cumulative_stream_usage: true so DeerFlow converts those snapshots into per-chunk deltas; the option is disabled by default and leaves usage unchanged when a stable completion id is unavailable. Reasoning models may also require the server to be started with --reasoning-parser .... If your local vLLM deployment accepts any non-empty API key, you can still set VLLM_API_KEY to a placeholder value.
CLI-backed provider examples:
models:
- name: gpt-5.4
display_name: GPT-5.4 (Codex CLI)
use: deerflow.models.openai_codex_provider:CodexChatModel
model: gpt-5.4
supports_thinking: true
supports_reasoning_effort: true
- name: claude-sonnet-4.6
display_name: Claude Sonnet 4.6 (Claude Code OAuth)
use: deerflow.models.claude_provider:ClaudeChatModel
model: claude-sonnet-4-6
max_tokens: 4096
supports_thinking: true
~/.codex/auth.jsonCLAUDE_CODE_OAUTH_TOKEN, ANTHROPIC_AUTH_TOKEN, CLAUDE_CODE_CREDENTIALS_PATH, or ~/.claude/.credentials.jsonacp_agents.codex, point it at a Codex ACP adapter such as npx -y @zed-industries/codex-acp npm install --global @minimax-ai/code
mcode login
   acp_agents:
     mcode:
       command: mcode
       args: ["acp"]
       description: MiniMax Code for implementation, refactoring, debugging, and repository tasks
       auto_approve_permissions: false
mcode must be on the Gateway process's PATH; installing it only on the Docker host does not make it available inside the Gateway container. DeerFlow invokes it through invoke_acp_agent in a per-thread ACP workspace and forwards enabled MCP servers. Keep auto_approve_permissions: false for untrusted tasks; enable it only when MCode must edit files or run commands and you trust the task.
eval "$(python3 scripts/export_claude_code_oauth.py --print-export)"
API keys can also be set manually in .env (recommended) or exported in your shell:
   OPENAI_API_KEY=your-openai-api-key
   TAVILY_API_KEY=your-tavily-api-key
Use the table below as a practical starting point when choosing how to run DeerFlow:
| Deployment target | Starting point | Recommended | Notes |
|---------|-----------|------------|-------|
| Local evaluation / make dev | 4 vCPU, 8 GB RAM, 20 GB free SSD | 8 vCPU, 16 GB RAM | Good for one developer or one light session with hosted model APIs. 2 vCPU / 4 GB is usually not enough. |
| Docker development / make docker-start | 4 vCPU, 8 GB RAM, 25 GB free SSD | 8 vCPU, 16 GB RAM | Image builds, bind mounts, and sandbox containers need more headroom than pure local dev. |
| Long-running server / make up | 8 vCPU, 16 GB RAM, 40 GB free SSD | 16 vCPU, 32 GB RAM | Preferred for shared use, multi-agent runs, report generation, or heavier sandbox workloads. |
Requires Docker Desktop / Docker Engine and Docker Compose v2.24+
(docker compose version). Older Compose clients cannot parse the optional
env_file syntax in docker/docker-compose-dev.yaml.
Development (hot-reload, source mounts):
make docker-init    # Pull sandbox image (only once or when image updates)
make docker-start   # Start services (auto-detects sandbox mode from config.yaml)
make docker-logs    # View logs
make docker-start starts provisioner only when config.yaml uses provisioner mode (sandbox.use: deerflow.community.aio_sandbox:AioSandboxProvider with provisioner_url).
Docker builds use the upstream uv registry by default. If you need faster mirrors in restricted networks, export UV_INDEX_URL=https://pypi.tuna.tsinghua.edu.cn/simple and NPM_REGISTRY=https://registry.npmmirror.com before running make docker-init or make docker-start.
Local AIO sandbox control traffic is always direct: loopback/private addresses,
single-label cluster hosts, and Docker/Podman internal hostnames do not inherit
HTTP_PROXY or HTTPS_PROXY. External sandbox FQDNs and public IPs still
honor environment proxy settings.
Backend processes automatically pick up config.yaml changes on the next config access, so model metadata updates do not require a manual restart during development.
Gateway runs use the top-level recursion_limit in config.yaml when an API
request does not provide one. The default is 100; valid per-request values
take precedence, and max_recursion_limit (default 1000) caps both. Changes
apply to the next run without restarting the Gateway. This top-level setting
applies to Gateway API runs; IM channel and embedded DeerFlowClient runs
retain their own defaults and per-call override paths.
The checkpoint storage settings database.checkpoint_channel_mode and
database.checkpoint_delta.snapshot_frequency (default 10) are exceptions:
both are frozen when the process first builds an agent (including through
DeerFlowClient) and require a process restart to change safely.
The optional database.checkpoint_cache section (delta channel mode only)
caches materialized checkpoint histories: type is memory (default) or
redis, and max_entries: 0 disables the cache. The redis backend is
Gateway/async-only; the sync TUI/embedded path supports memory only. The
cache is performance-only — results are identical with it disabled — so it is
never frozen and workers sharing one checkpoint database may safely run
different cache settings.
[!TIP]
On Linux, if Docker-based commands fail withpermission denied while trying to connect to the Docker daemon socket at unix:///var/run/docker.sock, add your user to thedockergroup and re-login before retrying. See CONTRIBUTING.md for the full fix.
Production (builds images locally, mounts runtime config and data):
make up     # Build images and start all production services
make down   # Stop and remove containers
Access: http://localhost:2026
make up waits for the Gateway /health endpoint before reporting success.
If the Gateway does not become healthy within the startup window, deployment
exits non-zero and prints the container status plus recent Gateway logs. The
production image starts from its already-built environment and never resolves
or installs Python dependencies at container startup.
For persistent deployments, configure database.backend as sqlite or
postgres. The selected backend is shared by the LangGraph checkpointer,
LangGraph Store, and DeerFlow application data. The deprecated checkpointer
section, when present, overrides the first two for backward compatibility.
Gateway startup automatically repairs the missing run-change schema affecting some existing databases (#5516). The repair preserves run history and existing change positions; downgrading the repair to its predecessor also retains the schema and positions required by that version.
For lightweight single-process event persistence, run_events.backend: jsonl
keeps Unicode message content intact, including line and paragraph separators.
Existing valid JSONL records remain readable without rewriting the files.
The unified nginx endpoint is same-origin by default and does not emit browser CORS headers. If you run a split-origin or port-forwarded browser client, set GATEWAY_CORS_ORIGINS to comma-separated exact origins such as http://localhost:3000; the Gateway then applies the CORS allowlist and matching CSRF origin checks.
Browser login uses HttpOnly session cookies. The login page offers a "keep me signed in" option that extends the browser session when the request is HTTPS (including trusted X-Forwarded-Proto: https) or localhost HTTP. The localhost exception uses the direct request Host and ignores forwarded host headers. Public HTTP deployments, including many temporary sandbox URLs, fall back to session cookies by default. DeerFlow never stores the password in browser storage; the UI may remember only the email address.
DeerFlow still uses Forwarded / X-Forwarded-* headers to recover the browser-facing scheme and origin behind a proxy. The bundled nginx sets X-Forwarded-Proto, but preserves an upstream HTTPS value and does not overwrite every forwarded header. Configure the outer trusted proxy to replace or strip client-supplied forwarding headers before traffic reaches DeerFlow.
[!IMPORTANT]
The Gateway still owns active run tasks in process, so production defaults to a single Gateway worker (GATEWAY_WORKERS=1). Multi-worker deployments require Postgres, the Redis stream bridge (stream_bridge.type: redis),run_ownership.heartbeat_enabled: true, andrun_events.backend: db; process-local memory/JSONL event stores cannot enforce singleton delivery receipts across workers. The bridge shares SSE delivery and boundedLast-Event-IDreplay across workers. When a valid reconnect cursor has been trimmed, or a subscriber that already established an empty-stream wait falls behind before its first delivery, Memory and Redis emit a machine-readable SSEgapevent instead of silently returning a partial replay; the Web UI reloads durable thread/event state and resumes from the retained tail. Lease reconciliation marks runs from dead workers as errors, persists their delivery receipts, publishes the terminal stream marker, schedules retained-stream cleanup, and updates the affected thread status. SSE,/wait, and internal stream consumers usestream_bridge.heartbeat_interval_seconds(default15) for idle liveness checks; changing it requires a Gateway restart. Malformed Redis reconnect IDs live-tail new events instead of replaying the retained buffer, and the rolling retained-buffer TTL (stream_ttl_seconds) remains a cleanup safety net rather than a run timeout. IM channel state and other process-local services still need their own
→ →
 →
 →
 →
 →
 →
 →