1
 →
An all-in-one, pure C++ inference engine for audio models, powered by ggml. Supports TTS, STT, VAD, voice conversion, music generation, and more, with highly optimized performance.
0xShug0/audio.cpp is an open-source project on GitHub, mainly written in C++. An all-in-one, pure C++ inference engine for audio models, powered by ggml. Supports TTS, STT, VAD, voice conversion, music generation, and more It currently holds 3,958 stars and 479 forks with 16 open issues, and was last pushed on 2026-11-03 (repository created 2026-06-23).
Git Homed tracks it on the Audio Trending board and on the AI Audio Trending list.
audio.cpp is a high-performance C++ audio inference framework built on top of ggml, designed to make modern local audio models practical, portable, and fast.
Tired of juggling a dozen Conda environments, hundreds of Python packages, and dependency conflicts just to try a few audio models? audio.cpp gives those paths a shared native runtime instead. Runs on Windows, Linux, and macOS, with support for NVIDIA, AMD, Apple Silicon, and CPU-only machines.
Lost in a sea of audio model names, papers, and codebases? Explore 100+ audio models in the Audio Model Architecture Atlas to see how they're built, what they share, and where they differ, whether you're learning or building your own.

Supported backends:
[!TIP]
> v0.9.4 highlights
> Experimental HIP kernels: Select--backend hip --backend-impl gfx1151_v1to try alternative AMD kernels. On the tested Strix Halo GPU, Q8 generation time fell by 76.7% for Irodori-TTS Small MF, 30.9% for Qwen3-TTS 1.7B VoiceDesign, and 14.0% for BreezeTTS2 versus default HIP. Despite its name,gfx1151_v1can also run on RDNA1/2, as well as RDNA3/4; available fast paths vary by architecture. Gains vary by model and hardware; the implementation is opt-in. See the HIP guide. Contributions are welcome: test other AMD GPUs, report model performance and correctness, or help improve the kernels. Thanks to AMD DevLab for providing hardware access!
> Metal optimizations: New SSM scan, convolution, and dataflow optimizations reduce RE-USE processing time by 56.5% on M4 Pro. Parakeet’s channel-contiguous subsampling and matrix projections reduce end-to-end processing time by 12.1–13.9%, with unchanged transcripts.
> Browser inference with WASM + WebGPU: Run supported models locally in the browser. On RTX 5090 in Chrome, measured throughput reaches 23.3× real time for Supertonic 3, 13.9× for Kokoro, 94.3× for SenseVoice ASR, and 25.0× for warmed LFM3-Audio ASR. See the tested models, settings, and performance table.
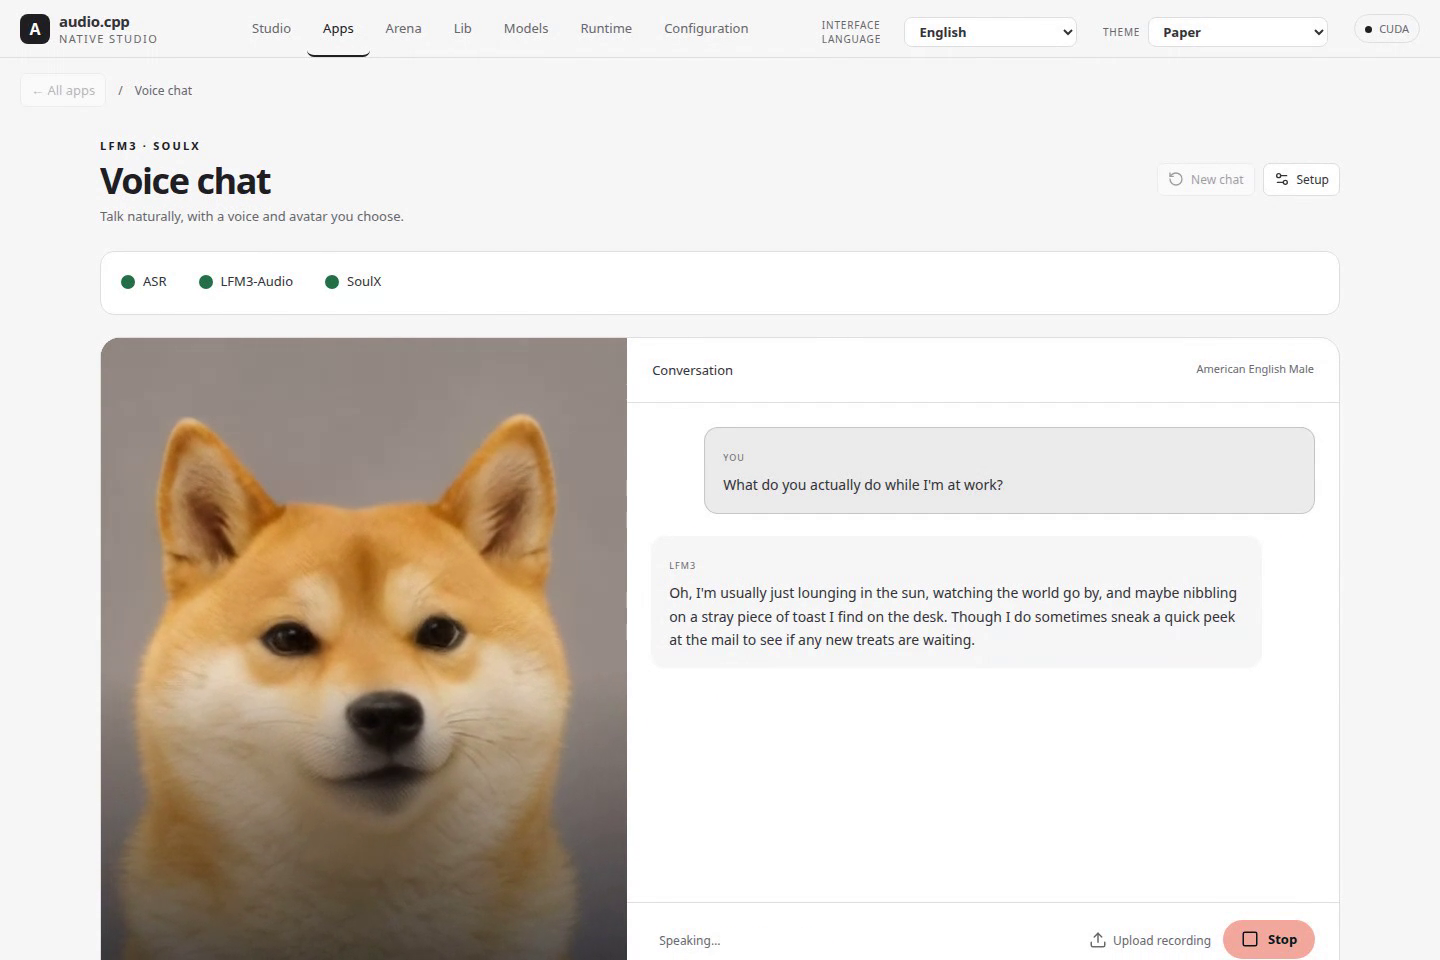
> Experimental streaming avatar voice chat: Talk to LFM3-Audio through the WebUI while SoulX-FlashHead animates your chosen portrait. Responses stream as text, speech, and synchronized head animation, with voice selection, adjustable speaking speed, and a customizable personality.
>>
audio.cpp is built for real end-to-end execution rather than one-off model demos. Its optimized, reusable building blocks support speech generation and recognition, separation, alignment, and multi-model workflows. Shared components make new models easier to integrate and let improvements benefit multiple model families while keeping inference efficient, maintainable, and portable.
⭐ 143 audio model families and 250+ variants. Run TTS, ASR, music generation, voice cloning, conversion, separation, and more locally through a shared CLI and server API.
⭐ Built-in WebUI. Generate and clone voices in Studio, compare models in Arena, manage models and voice libraries, and assemble narration with reusable speakers and passage editing in the TTS app.
⭐ Performance. Reusable sessions, cached graphs, and batched offline inference. Selected TTS paths run 1.8–8× faster than Python; tested Q8 packages deliver up to 1.53× speedup and 37% lower peak VRAM versus 16-bit weights (report). Supertonic 3 generates 10 hours of audio in 3 minutes on RTX 5090 (demo), while Nemotron 3.5 ASR matches WER at roughly ¼ the wall time in the TranscrIA benchmark. audio.cpp is among the fastest inference engines for streaming TTS latency on the Open TTS Leaderboard.
⭐ Portability. A native ggml runtime supporting CUDA, HIP/ROCm, Vulkan, Metal, WebGPU, SYCL, and CPU through common CLI and server interfaces.
⭐ Hardware-specific optimizations. ARM NEON acceleration, Rockchip RKNN component execution, experimental HIP kernels, and CUDA, Metal, and Vulkan optimizations. Model-specific perf_mode presets expose optional fast paths for supported hardware.
⭐ Parity. Validation tooling for comparing model outputs against Python reference implementations.
⭐ Integrations and deployment. Powers speech, music, and transcription in Unsloth Studio. Fun-ASR-Nano and SenseVoice can also be deployed through the FunASR platform.
audio.cpp would not be moving this quickly without generous contributors bringing in real fixes, new capabilities, and careful polish. See CONTRIBUTING.md for how to contribute and for a shout-out to the people already helping shape the project. Before starting a new model port, check the supported model table because several families are already implemented or under testing, and read the New Model PRs section in CONTRIBUTING.md. New ports should start under the community model source tree, where review is lighter than core models but still needs reproducible validation.
[!IMPORTANT]
2026-11-04 — Release v0.9.4: WebGPU support brings audio inference to the browser with WASM, and the WebUI gains streaming voice chat with animated SoulX avatars, cross-language dubbing, and voice-library export, import, and sorting. New models include Nemotron 3.5 Transcribe with CPU offload below 7 GB VRAM, LFM3-Audio, LFM D1-Omni, PocketTTS Small, SoulX-FlashHead, Real-time RE-USE, Magenta RealTime 2, Music Flamingo, Haas, and Underdog Bark 3, plus Irodori-TTS v4 Large. Experimental AMD kernel selection, new performance controls, and backend fixes improve speed, memory use, and compatibility. This release brings together community model ports, backend optimizations, and fixes shaped by real deployment reports.
2026-10-26 — Release v0.9.3: New speech models including Drama3, Ming 3.0 TTS/Audio Tiny, XTTS v2, Plapre 3, Gradium Phonon, and Earshot VAD, plus experimental LatentSync lip sync. Highlights include LoRA across 11 models, a TTS workspace, voice-cloning and dubbing recipes, perf_mode presets, lower memory use, and expanded HIP, ARM NEON, and Rockchip NPU support. Thanks to our contributors!
2026-10-15 — Release v0.9.2: New models include Voxtral TTS, TF-GridNet, MossFormer2, Hviske v6, FireRed VAD, AST, CED, and wake-word detection models. This release expands TTS streaming, adds multi-turn LFM2.5-Audio conversations, and improves model performance and compatibility. The WebUI gains a shared Voice Library and layout improvements. Downloadable C API libraries, Windows Vulkan portable builds, and packaged server configuration examples make integration easier. Thanks to everyone contributing code, testing, and feedback!
2026-09-30 - Release v0.9.0: 100+ audio models, an enhancement and denoising WebUI tab, speaker-tagged ASR, and performance and memory improvements. Explore the Architecture Atlas. Thanks to our community!
2026-06-25 to 2026-09-23 (releases 0.1 to 0.8): audio.cpp grew to 80+ model families and 120+ variants across TTS, ASR, music generation, voice conversion, separation, and speech analysis. Major additions included the native WebUI and Arena, GGUF packaging, LoRA adapters, streaming, and CUDA/Metal performance improvements, alongside Vulkan and experimental HIP support. The C ABI, Colab integration, MP3/HTTPS frontends, and models such as YuE2 and SheetSage2 expanded integration and audio-to-score workflows.
Task tags: TTS text to speech, Clone voice cloning, VC voice conversion, S2S speech-to-speech, ASR speech recognition, Classify audio classification, Wake wake-word detection, Align forced alignment, VAD voice activity detection, Diar speaker diarization, Codec audio codec, Sep source separation, MIDI audio-to-symbolic MIDI/events, Music music/song generation, SFX sound effects, Video video generation, Edit audio/music editing, Design voice design, Dialogue multi-speaker dialogue TTS, Ctrl TTS/clone voice control such as emotion, style, instruction, caption, or non-verbal tag control.
Runtime tags summarize the supported loading paths. GGUF package precision varies by model and release; check the audio.cpp GGUF repo or docs/gguf.md for the exact package list. Bundled means the tiny runtime asset ships under assets/framework/models and needs no separate model download. Stream means the family exposes a streaming server/session path. LoRA means adapter loading is supported in audio.cpp; see the LoRA guide for supported formats and usage.
Model weights keep the license of their original release, which is separate from audio.cpp's own license. docs/model_licenses.md lists that license per family, and whether it allows commercial use.
| Family | Task | Lang | Variants | Runtime |
|---|---|---|---|---|
| breeze_tts | TTS, Clone, Design, Ctrl | zh, en | BreezeTTS 2 instruction-conditioned TTS and prompt-audio voice cloning | GGUF BF16/Q8/Q4_0, Stream |
| chatterbox | TTS, Clone, VC| ar, da, de, el, en, es, fi, fr, hi, it, ko, ms, nl, no, pl, pt, sv, sw, tr | Chatterbox with 0.5B backbone | GGUF 16/Q8 |
| confucius4_tts | TTS, Clone | zh, en, ja, ko, de, fr, es, id, it, th, pt, ru, ms, vi | Confucius4-TTS multilingual voice cloning | GGUF F32, Stream |
| cosyvoice3 | TTS, Clone | zh, en, ja, ko, de, es, fr, it, ru, yue | Fun-CosyVoice3 zero-shot, cross-lingual, and instruction-conditioned TTS | GGUF F32/Q8, LoRA |
| dots_tts | TTS, Clone, Edit, Ctrl | multilingual | DotTTS SOAR
DotTTS MeanFlow
DotTTS Edit | GGUF 16/Q8, Stream |
| dramabox | TTS, Clone | en | DramaBox expressive TTS and voice cloning | GGUF Q8 |
| fish_audio | TTS, Clone, Ctrl | auto, en, zh | Fish Audio S2 Pro | GGUF 16/Q8, Stream, LoRA |
| firered_audio | ASR, TTS, Clone, Design, Ctrl | zh, en | FireRedAudio multimodal speech/audio model with ASR, understanding, cloning, design, and edit paths | GGUF original/Q8 |
| fireredtts3 | TTS, Clone, Design, Ctrl | 24 langs + 21 zh dialects | FireRedTTS3 Base
FireRedTTS3 Instruct/Voicedesign | GGUF original/Q8 |
| gradium_phonon | TTS | en | Gradium Phonon 31m English | GGUF Q8, Safetensors, Stream |
| higgs_audio_tts | TTS, Clone, Ctrl | auto | Higgs Audio v3 TTS 4B | GGUF 16/Q8, Stream |
| index_tts2 | TTS, Clone, Ctrl | zh, en, ja, es, ar | IndexTTS-2
IndexTTS-2.5 | GGUF 16/Q8 |
| kokoro_tts | TTS | en-us, en-gb, es, fr, hi, it, ja, pt-br, zh | Kokoro 82M, 54 preset voices | Safetensors, local GGUF BF16/Q8, Stream |
| kugelaudio | TTS | European multilingual | KugelAudio-0-Open, four preset voices | GGUF BF16 / Q8_0 / Q4_K, Stream |
| irodori_tts | TTS, Clone, Design, Ctrl | ja | Irodori-TTS-v4.1-Small (RF and MF)
Irodori-TTS-v4.1-Anime
Irodori-TTS-500M-v3
Irodori-TTS-600M-v3-VoiceDesign | GGUF 16/Q8 |
| magpie_tts | TTS | ar-AE, ar-MSA, ar-SA, de, en, es, fr, hi, it, ko, pt-BR, vi, zh | NVIDIA MagpieTTS Multilingual 357M (v2607) with baked speaker prompts and NanoCodec decode | GGUF original/Q8 |
| maya1 | TTS, Design, Ctrl | en | Maya1 expressive TTS with natural-language voice design, inline emotion tags, and SNAC decoding | GGUF original/Q8 |
| ming3_tts | TTS, Clone, Design, Ctrl | zh, en, ja, ko, de, fr, es | Ming 3.0 TTS 0.5B | GGUF BF16/Q8, Stream |
| miotts | TTS, Clone | en, ja | MioTTS-1.7B | GGUF 16/Q8 |
| moss_tts_local | TTS, Clone, Ctrl | auto, optional language hint | MOSS-TTS-Local-Transformer-v1.5 | GGUF 16/Q8 |
| moss_tts_nano | TTS, Clone | auto | MOSS-TTS-Nano-100M | GGUF 16/Q8, Stream |
| neutts | TTS, Ctrl | en | NeuTTS 2E with built-in speaker prompts and emotion control | GGUF original precision, Stream |
| omnivoice | TTS, Clone, Design, Ctrl | 646+ langs | OmniVoice, Qwen3-0.6B based
VoiceTut-TTS (Egyptian Arabic fine-tune) | GGUF 16/Q8, Stream |
| personaplex | Dialogue, S2S | en | PersonaPlex 7B v1 speech-to-speech conversational model with packaged voice/persona prompts | GGUF Q4/Q8, Stream |
| plapre | TTS, Clone, Ctrl, Edit | da | Plapre 3, five preset voices | GGUF F32/BF16, Stream |
| pocket_tts | TTS, Clone | en, fr, de, it, pt, es | PocketTTS-100M English/French/German/Italian/Portuguese/Spanish | GGUF 16/Q8, Stream |
| pocket_tts_small | TTS, Clone | en | PocketTTS Small 18M/7M/2M, base and ReFL | GGUF F32, Stream |
| qwen3_tts | TTS, Clone, Design, Ctrl | zh, en, fr, de, it, ja, ko, pt, ru, es | Qwen3-TTS-12Hz-0.6B-Base
Qwen3-TTS-12Hz-1.7B-Base
Qwen3-TTS-12Hz-1.7B-CustomVoice
Qwen3-TTS-12Hz-1.7B-VoiceDesign | GGUF 16/Q8, Stream, LoRA |
| supertonic | TTS | en, ko, ja, ar, bg, cs, da, de, el, es, et, fi, fr, hi, hr, hu, id, it, lt, lv, nl, pl, pt, ro, ru, sk, sl, sv, tr, uk, vi, na | Supertonic 3 | GGUF F32, Stream |
| vibevoice | TTS, Dialogue | en, zh | VibeVoice-1.5B
VibeVoice-7B | GGUF 16/Q8, Stream, LoRA |
| voxcpm2 | TTS, Clone, Design, Ctrl | ar, da, de, el, en, es, fi, fr, he, hi, id, it, ja, km, ko, lo, ms, my, nl, no, pl, pt, ru, sv, sw, th, tl, tr, vi, zh | VoxCPM2-2B, 48 kHz
VocalRender-Pro (score-conditioned singing) | GGUF 16/Q8, Stream, LoRA |
| voxtral_tts | TTS | en, fr, es, de, it, pt, nl, ar, hi | Voxtral-4B-TTS-2603, 20 embedded preset voices | GGUF BF16/Q8, Stream |
| Family | Task | Lang | Variants | Runtime |
|---|---|---|---|---|
| ast_audioset | Classify | language agnostic | MIT AST AudioSet, 527 classes | GGUF F32 |
| ced | Classify | language agnostic | CED Tiny
CED Mini
CED Small
CED Base
527 AudioSet classes | GGUF F32 |
| audio_flamingo | ASR, Audio understanding | en | Audio Flamingo 3
Audio Flamingo Next
Music Flamingo 2601
SpotSound (LoRA temporal grounding) | GGUF BF16/Q8/Q4, LoRA |
| canary_asr | ASR, Translate | en, de, es, fr | Canary 180M Flash | GGUF F32/Q8 |
| citrinet_asr | ASR | en | Citrinet-256 | GGUF Q8 |
| cohere_asr | ASR | en, fr, de, es, it, pt, nl, pl, el, ar, ja, zh, vi, ko | Cohere Transcribe 03-2026 | GGUF BF16/Q8/Q4_0 |
| crisperwhisper | ASR, Align | 99 language codes | CrisperWhisper 2.0 Large | GGUF BF16/Q8, Stream |
| gigaam_asr | ASR | ru, kk, ky, uz, en | GigaAM v3 CTC
GigaAM v3 RNN-T
GigaAM v3 E2E CTC
GigaAM v3 E2E RNN-T
GigaAM Multilingual CTC
GigaAM Multilingual Large CTC | GGUF F16/F32 |
| fun_asr_nano | ASR | auto, zh, en, ja | Fun-ASR-Nano-2512 | GGUF 16/Q8 |
| higgs_audio_stt | ASR | en | Higgs Audio v3 STT | GGUF 16/Q8, Stream |
| hviske_asr | ASR | da | Hviske v5.3 | GGUF Q8 |
| hviske_asr_v6 | ASR | da | Hviske v6 | GGUF BF16 / Q8 |
| index_echo | ASR, Translate | zh → en, es, ja | Index-Echo-S2TT 2B
Index-Echo-S2TT 9B | GGUF original/Q8_0/Q4_K |
| lfm_d1_omni | Classify | multilingual | d1-Omni-2B calibrated audio decisions with named yes/no, choice, score, and numeric-estimate questions | GGUF Q8_0/F16/BF16 |
| marblenet_vad | VAD | lang agnostic | MarbleNet VAD | Bundled |
| micro_wake_word | Wake | model dependent | microWakeWord MixedNet TFLite models converted to GGUF | GGUF F32, Stream |
| ming3_audio | ASR, Understanding, TTS, Clone, S2S | zh, en | Ming 3.0 Audio Tiny | GGUF BF16/Q8_0/Q4_K |
| open_wake_word | Wake | en | OpenWakeWord Alexa | GGUF F32, Stream |
| firered_vad | VAD | lang agnostic | FireRed VAD / Stream-VAD | GGUF F32/F16/Q8, Stream |
| pulsevad | VAD | lang agnostic | PulseVAD 2.1K Student / 81K Teacher | GGUF F32 |
| moonshine_asr | ASR | en | Moonshine Streaming Tiny/Small/Medium | GGUF Q8, Stream |
| moss_transcribe_diarize | ASR | auto, 50+ languages | MOSS-Transcribe-Diarize with speaker labels and timestamps | GGUF BF16/Q8/Q4_K, Stream |
| nemotron_3_diar | Diar | multilingual | NVIDIA Nemotron 3 Diarization with eight-speaker arrival-order diarization | GGUF BF16, Batch, Stream |
| nemotron_asr | ASR | 100+ ASR prompt codes incl. auto | Nemotron 3.5 ASR Streaming 0.6B | GGUF 16/Q8, Stream |
| niagara_asr | ASR | en | Niagara 19M Batch English
Niagara 38M Batch English | GGUF F32 |
| owsm | ASR, Translate | 151 language codes | OWSM v4 Base 102M
OWSM v4 Small 370M
OWSM v4 Medium 1B | GGUF F32 / Q8_0 / Q4_K (Small, Medium) |
| owsm_ctc | ASR, Translate | 151 language codes | OWSM-CTC v4 1B | GGUF F32 / Q8_0 |
| qwen3_asr | ASR | zh, en, yue, ar, de, fr, es, pt, id, it, ko, ru, th, vi, ja, tr, hi, ms, nl, sv, da, fi, pl, cs, fil, fa, el, ro, hu, mk | Qwen3-ASR-0.6B
Qwen3-ASR-1.7B-hf
QwenCleo-ASR (Egyptian Arabic fine-tune) | GGUF 16/Q8, Stream, LoRA |
| qwen3_forced_aligner | Align | zh, yue, en, de, es, fr, it, pt, ru, ko, ja | Qwen3-ForcedAligner-0.6B | GGUF 16/Q8 |
| samsone | Audio understanding | en | SAMSONE 99M
SAMSONE 134M
SAMSONE 356M | GGUF BF16/Q8 |
| silero_vad | VAD | lang agnostic | Silero VAD | Bundled, Stream |
| sherpa_kws | Wake | model dependent | sherpa-onnx streaming Zipformer keyword spotting | GGUF F32, Stream |
| smart_turn | Turn detection | auto | Smart Turn v3.2 | GGUF F32 |
| sortformer_diar | Diar | en | Sortformer-4spk-v1 | - |
| vibevoice_asr | ASR | auto | VibeVoice ASR | GGUF 16/Q8 |
| vibevoice_asr_streaming | ASR | en, zh, es, pt, de, ja, ko, fr, ru, it | VibeVoice ASR Streaming 7B/1.5B with persistent decoder state and speaker turns | GGUF BF16/Q8/Q4, Stream |
| voxtral_realtime | ASR | auto | Voxtral-Mini-4B-Realtime-2602 | GGUF 16/Q8/Q4, Stream |
| Family | Task | Lang | Variants | Runtime |
|---|---|---|---|---|
| apollo | S2S | lang agnostic | Apollo music restoration | GGUF F32 |
| audiosr | S2S | lang agnostic | AudioSR Basic audio super-resolution package | GGUF F32 |
| bs_roformer | Sep | lang agnostic | BS-RoFormer vocal separation checkpoints | GGUF Q8 |
| builtin_audio_utils | S2S | lang agnostic | RNNoise
DeepFilterNet2
ZipEnhancer
GTCRN Streaming
GTCRN DNS3
GTCRN VCTK
FlashSR | Safetensors |
| controlfoley | SFX | auto | ControlFoley 44 kHz multimodal Foley generation from text, video, and reference audio conditioning | GGUF F32/Q8 |
| htdemucs | Sep | lang agnostic | HTDemucs
HTDemucs_ft
HTDemucs_6stems | GGUF 16/Q8 |
| meanvc2 | VC | lang agnostic | MeanVC2 120 ms/40 ms zero-shot voice conversion | GGUF F32/Q4, Stream |
| mel_band_roformer | Sep | lang agnostic | Mel-Band RoFormer MLX vocal separation variants | GGUF 16/Q8 |
| miocodec | Codec, VC | lang agnostic | MioCodec v2, 25 Hz, 44.1 kHz | GGUF 16/Q8 |
| mossformer2 | Sep | lang agnostic | MossFormer2 SS 16K two-speaker separation | GGUF F32 |
| muscriptor | MIDI | music | MuScriptor Small/Medium/Large audio-to-symbolic transcription | GGUF F32, Stream |
| rvc | VC | lang agnostic | RVC F16 GGUF with packaged v1/v2 voices and optional retrieval blending | GGUF 16 |
| sam_audio | S2S | lang agnostic | SAM Audio Small
SAM Audio Base
SAM Audio Large | GGUF F32/BF16/Q8 |
| seed_vc | VC | lang agnostic | SeedVC XLS-R + HiFT
SeedVC Whisper-small + BigVGAN | GGUF 16/Q8 |
| sheetsage2 | MIDI | music | SheetSage2 audio-to-ABC score transcription | GGUF orig |
| sidon | S2S | lang agnostic | Sidon v0.1 single-speaker speech restoration | GGUF F32 |
| tf_gridnet | Sep | lang agnostic | TF-GridNet WSJ0-2mix two-speaker separation | GGUF F32 |
| tone_color_vc | VC | lang agnostic | Tone Color VC | GGUF F32/F16 |
| universr | S2S | lang agnostic | UniverSR Audio and Speech super-resolution | GGUF F32 |
| Family | Task | Lang | Variants | Runtime |
|---|---|---|---|---|
| ace_step | Music, Edit | 50+ langs | ACE-Step 1.5 Turbo
ACE-Step 1.5 Base
ACE-Step 1.5 XL Turbo
ACE-Step 1.5 XL SFT | GGUF 16, LoRA |
| heartmula | Music | zh, en, ja, ko, es | HeartMuLa-oss-3B with HeartCodec-oss | GGUF 16/Q8 |
| magenta_realtime_2 | Music | music | Magenta RealTime 2 Small (230M)
Magenta RealTime 2 Base (2.4B) | GGUF F16/Q8_0, Stream |
| midashenglm_gen | Music, SFX | auto | MiDashengLM-Gen structured-prompt generation for speech, music, sound effects, and ambience | GGUF F32/Q8 |
| minimax_h3 | Video, Music, TTS/Dialogue | auto | MiniMax-H3 Q4_K with optional INT8 ConvRot DiT | GGUF Q4/INT8 |
| minimax_music3 | Music | auto | MiniMax Music 3 text-to-music generation with lyrics conditioning | GGUF Q4/Q8 |
| moss_soundeffect | SFX | en, zh | MOSS-SoundEffect v2 text-conditioned sound effects | GGUF BF16/Q8 |
| mulacover | Music | multilingual | MuLaCover cover-song generation from reference audio or melody/chord MIDI, with new lyrics and style | GGUF 16/Q8 |
| soulx_flashhead | Audio-to-video | lang agnostic | SoulX-FlashHead Lite audio-driven portrait video generation | GGUF Q8/BF16, Stream |
| stable_audio | Music, SFX, Edit | en | Stable Audio 3 Small Music
Stable Audio 3 Smal
→ →
 →
 →
 →
 →
 →
 →